Camera-controlled novel view synthesis: additional cases
Mundo against Stable Virtual Camera [1], Gen3C [2], FrameCrafter [3], Holo4D [4], TrajectoryCrafter [5], AnySplat [6], FramePack [7], MiniMax H3 [8] and Code Video Model [9] on ten further trajectories each of ScanNet++ and Tanks and Temples: each method renders a ground-truth camera trajectory of a real scene from its context input.
Setup
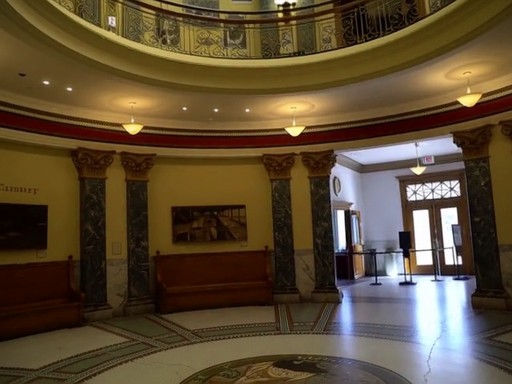
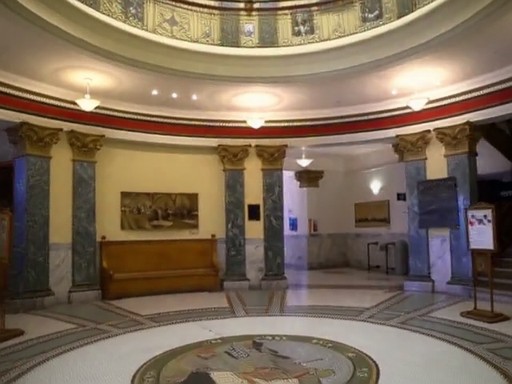
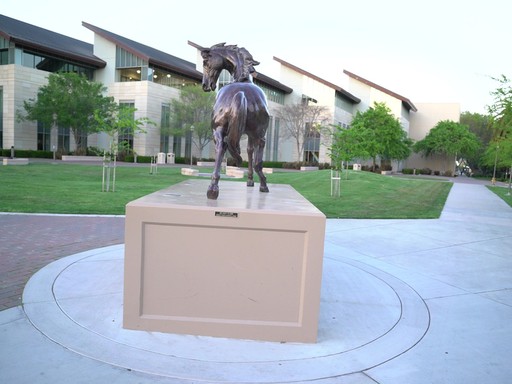
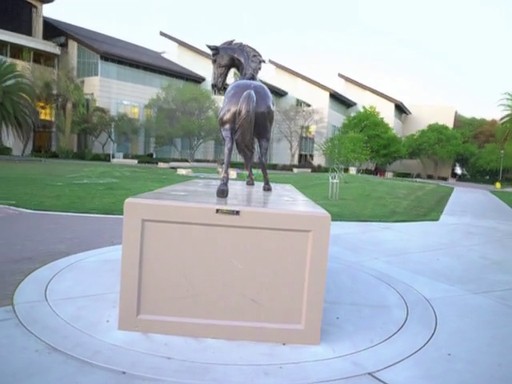
- Cases. Ten further trajectories each of ScanNet++ [10] and Tanks and Temples [11], under the protocol of the main evaluation. ScanNet++: one trajectory in each of ten further test scenes, drawn with the same seed from the same scene list as the first ten test scenes, which are the first ten draws. Tanks and Temples: Ballroom (third trajectory), Ballroom (fourth trajectory), Church (third trajectory), Church (fourth trajectory), Courtroom (third trajectory), Horse, Meetingroom (third trajectory), Museum (second trajectory), Museum (third trajectory), Playground (second trajectory). Trajectories in a scene already used do not overlap the earlier ones. A trajectory is a real capture segment of thirteen keyframes that the context views cover (covisibility at least 0.85).
- Inputs. Every method receives the ground-truth target trajectory and no depth, and runs exactly as in the main evaluation. Mundo, Stable Virtual Camera, Gen3C and FrameCrafter receive the same context views with their ground-truth poses and intrinsics (nine for ScanNet++, eight for Tanks and Temples). AnySplat receives these views without poses and predicts their cameras; the target trajectory enters its frame relative to the trajectory start, scaled by the median ratio of predicted to ground-truth distances between the context cameras. FrameCrafter generates every target keyframe in a separate call from all context views, at 544×720 for the 4:3 ScanNet++ views and 480×832 for Tanks and Temples; it renders the thirteen keyframes only, so the temporal metrics are not computed for it. Holo4D receives a 49-frame video that starts at the trajectory start and runs backwards through the capture before it: the raw capture video for Tanks and Temples, the released frames for ScanNet++. TrajectoryCrafter receives the first context view, which is the trajectory start. FramePack receives the context views as its frame history and MiniMax H3 receives them as reference images; both take no camera input and follow a text timeline of the trajectory. Code Video Model [9] receives Mundo's proxy video, the context views and the scene description, without camera parameters; the proxy conditions the first five of twenty denoising steps. Baselines run their official code and default settings; Mundo runs its release pipeline with default settings.
- Ground truth. ScanNet++ uses its released cameras. Tanks and Temples releases no cameras for its image sets, so one Pi3X pass over all frames of a scene gives the cameras for every method.
- Fidelity. Frames are cropped to a shared 4:3 canvas of 512×384 with identical rays for every method. PSNR, SSIM and LPIPS (VGG) against the real keyframes 1 to 12.
- Realism. FID [12] and FD-DINOv2 [13] between the set of generated keyframes and the set of real keyframes of the same cases, with KID on DINOv2 features (multiplied by 1000; a negative value means the two sets are closer than the estimator can resolve).
- Content. DINO similarity: cosine similarity of DINOv2 features between each generated keyframe and the real keyframe at the same camera. Context similarity (additional table): the highest similarity of a generated keyframe to any context view.
- VBench [14]. Imaging quality (MUSIQ-SPAQ) on the keyframes, and subject and background consistency over all frames of each video. Methods without camera input keep the view nearly still, which raises the consistency scores. Additional metrics: DISTS [15], VBench aesthetic quality, Q-Align [16], and PSNR and LPIPS over the pixels that the context views see.
- Camera following. Fitted: Pi3X estimates the cameras of the thirteen keyframes of each video, aligned to the ground truth with a similarity transform; ATE is divided by the extent of the trajectory. Anchored: Pi3X estimates the context views together with the keyframes, and the transform that maps the context estimates onto their ground truth places the generated cameras. TSED [17] counts consecutive frame pairs whose matches satisfy the epipolar geometry of the target cameras.
Results
best in columnsecond bestA number in parentheses is the count of cases when a method lacks some; such entries are not ranked.
Additional cases (ten per dataset)
| Method | ScanNet++ (10) | Tanks and Temples (10) | ||||||
|---|---|---|---|---|---|---|---|---|
| PSNR ↑ | SSIM ↑ | LPIPS ↓ | FID ↓ | PSNR ↑ | SSIM ↑ | LPIPS ↓ | FID ↓ | |
| FramePack [7] | 8.88 | 0.413 | 0.694 | 165.7 | 10.22 | 0.188 | 0.658 | 122.4 |
| MiniMax H3 [8] | 9.61 | 0.400 | 0.672 | 116.0 | 10.55 | 0.217 | 0.670 | 105.9 |
| Code Video Model [9] | 9.97 | 0.413 | 0.639 | 95.5 | 11.04 | 0.232 | 0.638 | 102.3 |
| AnySplat [6] | 12.27 | 0.489 | 0.543 | 144.1 | 10.83 | 0.223 | 0.599 | 129.5 |
| TrajectoryCrafter [5] | 10.02 | 0.451 | 0.660 | 175.8 | 11.48 | 0.252 | 0.645 | 155.1 |
| Holo4D [4] | 11.90 | 0.519 | 0.561 | 120.2 | 12.64 | 0.287 | 0.545 | 90.8 |
| Stable Virtual Camera [1] | 15.41 | 0.561 | 0.400 | 68.0 | 13.24 | 0.301 | 0.477 | 70.8 |
| Gen3C [2] | 15.15 | 0.583 | 0.463 | 115.9 | 13.01 | 0.302 | 0.541 | 103.1 |
| FrameCrafter [3] | 15.14 | 0.570 | 0.427 | 69.5 | 13.60 | 0.297 | 0.495 | 69.1 |
| Mundo | 15.83 | 0.582 | 0.398 | 56.5 | 14.00 | 0.319 | 0.474 | 56.2 |
Additional and original cases together (twenty per dataset)
| Method | ScanNet++ (20) | Tanks and Temples (20) | ||||||
|---|---|---|---|---|---|---|---|---|
| PSNR ↑ | SSIM ↑ | LPIPS ↓ | FID ↓ | PSNR ↑ | SSIM ↑ | LPIPS ↓ | FID ↓ | |
| FramePack [7] | 8.99 | 0.419 | 0.681 | 128.6 | 10.43 | 0.211 | 0.652 | 108.2 |
| MiniMax H3 [8] | 9.62 | 0.423 | 0.664 | 91.9 | 11.06 | 0.241 | 0.651 | 78.1 |
| Code Video Model [9] | 9.85 | 0.419 | 0.648 | 83.0 | 11.36 | 0.249 | 0.632 | 76.5 |
| AnySplat [6] | 11.93 | 0.484 | 0.564 | 143.6 | 11.00 | 0.245 | 0.597 | 123.9 |
| TrajectoryCrafter [5] | 10.32 | 0.469 | 0.655 | 137.4 | 11.91 | 0.287 | 0.635 | 124.4 |
| Holo4D [4] | 11.97 | 0.531 | 0.556 | 104.0 | 13.19 | 0.317 | 0.543 | 77.3 |
| Stable Virtual Camera [1] | 15.28 | 0.584 | 0.409 | 58.6 | 13.59 | 0.329 | 0.466 | 54.5 |
| Gen3C [2] | 14.95 | 0.593 | 0.475 | 101.7 | 13.76 | 0.342 | 0.511 | 81.8 |
| FrameCrafter [3] | 14.74 | 0.579 | 0.443 | 62.6 | 14.25 | 0.336 | 0.473 | 53.0 |
| Mundo | 15.87 | 0.602 | 0.401 | 50.0 | 14.70 | 0.351 | 0.463 | 47.4 |
ScanNet++ [10]: all metrics (10 cases)
| Method | Fidelity to the ground truth | Content | Realism (distribution) | VBench | ||||||
|---|---|---|---|---|---|---|---|---|---|---|
| PSNR ↑ | SSIM ↑ | LPIPS ↓ | DINO sim. ↑ | FD-DINOv2 ↓ | KID-DINOv2 ×10³ ↓ | FID ↓ | Imaging ↑ | Subject ↑ | Background ↑ | |
| Mundo | 15.83 | 0.582 | 0.398 | 0.907 | 298 | -218 | 56.5 | 64.0 | 0.812 | 0.918 |
| Stable Virtual Camera [1] | 15.41 | 0.561 | 0.400 | 0.885 | 378 | -41 | 68.0 | 74.3 | 0.799 | 0.877 |
| Gen3C [2] | 15.15 | 0.583 | 0.463 | 0.686 | 951 | 709 | 115.9 | 53.4 | 0.786 | 0.905 |
| FrameCrafter [3] | 15.14 | 0.570 | 0.427 | 0.857 | 433 | -83 | 69.5 | 61.5 | – | – |
| Holo4D [4] | 11.90 | 0.519 | 0.561 | 0.553 | 1096 | 768 | 120.2 | 57.5 | 0.785 | 0.900 |
| TrajectoryCrafter [5] | 10.02 | 0.451 | 0.660 | 0.352 | 1807 | 2087 | 175.8 | 53.5 | 0.804 | 0.899 |
| AnySplat [6] | 12.27 | 0.489 | 0.543 | 0.738 | 830 | 733 | 144.1 | 51.1 | 0.784 | 0.896 |
| FramePack [7] | 8.88 | 0.413 | 0.694 | 0.416 | 1573 | 1652 | 165.7 | 63.2 | 0.936 | 0.948 |
| MiniMax H3 [8] | 9.61 | 0.400 | 0.672 | 0.586 | 828 | 532 | 116.0 | 67.8 | 0.826 | 0.912 |
| Code Video Model [9] | 9.97 | 0.413 | 0.639 | 0.678 | 702 | 355 | 95.5 | 69.4 | 0.824 | 0.911 |
| Real keyframes reference / estimator floor | – | – | – | 1.000 | – | – | – | 64.6 | – | – |
Tanks and Temples [11]: all metrics (10 cases)
| Method | Fidelity to the ground truth | Content | Realism (distribution) | VBench | ||||||
|---|---|---|---|---|---|---|---|---|---|---|
| PSNR ↑ | SSIM ↑ | LPIPS ↓ | DINO sim. ↑ | FD-DINOv2 ↓ | KID-DINOv2 ×10³ ↓ | FID ↓ | Imaging ↑ | Subject ↑ | Background ↑ | |
| Mundo | 14.00 | 0.319 | 0.474 | 0.935 | 219 | -180 | 56.2 | 71.2 | 0.858 | 0.921 |
| Stable Virtual Camera [1] | 13.24 | 0.301 | 0.477 | 0.894 | 349 | 7 | 70.8 | 74.3 | 0.854 | 0.922 |
| Gen3C [2] | 13.01 | 0.302 | 0.541 | 0.724 | 885 | 896 | 103.1 | 62.8 | 0.824 | 0.900 |
| FrameCrafter [3] | 13.60 | 0.297 | 0.495 | 0.845 | 467 | 49 | 69.1 | 74.7 | – | – |
| Holo4D [4] | 12.64 | 0.287 | 0.545 | 0.747 | 811 | 641 | 90.8 | 69.7 | 0.838 | 0.927 |
| TrajectoryCrafter [5] | 11.48 | 0.252 | 0.645 | 0.514 | 1559 | 2131 | 155.1 | 57.9 | 0.836 | 0.905 |
| AnySplat [6] | 10.83 | 0.223 | 0.599 | 0.765 | 817 | 1240 | 129.5 | 65.2 | 0.826 | 0.912 |
| FramePack [7] | 10.22 | 0.188 | 0.658 | 0.652 | 1021 | 1255 | 122.4 | 76.3 | 0.981 | 0.982 |
| MiniMax H3 [8] | 10.55 | 0.217 | 0.670 | 0.690 | 730 | 636 | 105.9 | 70.5 | 0.864 | 0.926 |
| Code Video Model [9] | 11.04 | 0.232 | 0.638 | 0.784 | 578 | 397 | 102.3 | 71.4 | 0.886 | 0.933 |
| Real keyframes reference / estimator floor | – | – | – | 1.000 | – | – | – | 76.4 | – | – |
Additional perceptual metrics (20 cases)
| Method | Covisible PSNR ↑ | Non-covisible LPIPS ↓ | DISTS ↓ | KID ×10³ ↓ | Context sim. ↑ | Aesthetic ↑ | Q-Align ↑ | Sharpness / GT →1 |
|---|---|---|---|---|---|---|---|---|
| Mundo | 14.99 | 0.472 | 0.157 | 1.0 | 0.796 | 5.30 | 3.51 | 0.41 |
| Stable Virtual Camera [1] | 14.46 | 0.491 | 0.156 | 1.0 | 0.787 | 5.71 | 3.96 | 0.90 |
| Gen3C [2] | 14.20 | 0.547 | 0.225 | 13.4 | 0.664 | 5.06 | 3.00 | 0.32 |
| FrameCrafter [3] | 14.46 | 0.516 | 0.165 | 0.9 | 0.753 | 5.45 | 3.59 | 0.41 |
| Holo4D [4] | 12.33 | 0.592 | 0.241 | 5.9 | 0.679 | 5.12 | 3.28 | 0.37 |
| TrajectoryCrafter [5] | 10.78 | 0.677 | 0.313 | 23.7 | 0.518 | 4.75 | 2.73 | 0.17 |
| AnySplat [6] | 12.23 | 0.659 | 0.252 | 26.5 | 0.705 | 4.56 | 2.52 | 0.92 |
| FramePack [7] | 9.57 | 0.670 | 0.290 | 9.9 | 0.888 | 5.43 | 3.94 | 0.88 |
| MiniMax H3 [8] | 10.07 | 0.667 | 0.273 | 7.0 | 0.847 | 5.27 | 3.58 | 0.49 |
| Code Video Model [9] | 10.48 | 0.640 | 0.244 | 5.1 | 0.855 | 5.61 | 3.57 | 0.49 |
| Real keyframes reference / estimator floor | – | – | – | – | 0.802 | 5.59 | 3.91 | – |
Camera following and temporal behaviour (20 cases)
| Method | Fitted (Sim(3)) | Anchored by the context views | Temporal | ||||
|---|---|---|---|---|---|---|---|
| ATE rel. ↓ | RotErr (°) ↓ | ATE (m) ↓ | Rot (°) ↓ | TSED ↑ | Flicker ↑ | Smoothness ↑ | |
| Mundo | 0.041 | 3.16 | 1.172 | 12.73 | 0.980 | 0.926 | 0.986 |
| Stable Virtual Camera [1] | 0.039 | 2.91 | 1.111 | 12.03 | 0.988 | 0.917 | 0.979 |
| Gen3C [2] | 0.049 | 3.91 | 1.476 | 13.79 | 0.961 | 0.927 | 0.984 |
| FrameCrafter [3] | 0.100 | 5.35 | 1.162 | 14.17 | – | – | – |
| Holo4D [4] | 0.129 | 22.10 | 2.040 | 37.97 | 0.562 | 0.896 | 0.949 |
| TrajectoryCrafter [5] | 0.154 | 26.05 | 2.580 | 47.13 | 0.508 | 0.910 | 0.965 |
| AnySplat [6] | 0.023 | 2.13 | 1.467 | 13.42 | 0.998 | 0.925 | 0.987 |
| FramePack [7] | 0.146 | 60.08 | 2.375 | 71.05 | 0.481 | 0.990 | 0.996 |
| MiniMax H3 [8] | 0.161 | 50.48 | 2.537 | 62.81 | 0.368 | 0.936 | 0.983 |
| Code Video Model [9] | 0.127 | 38.57 | 2.997 | 46.85 | 0.523 | 0.936 | 0.981 |
| Real keyframes reference / estimator floor | 0.014 | 1.75 | 0.955 | 10.91 | – | – | – |
Keyframes
Ground truthMundoStable Virtual CameraGen3CFrameCrafterHolo4DTrajectoryCrafterAnySplatFramePackMiniMax H3Code Video Model
ScanNet++ · 252652d5ba
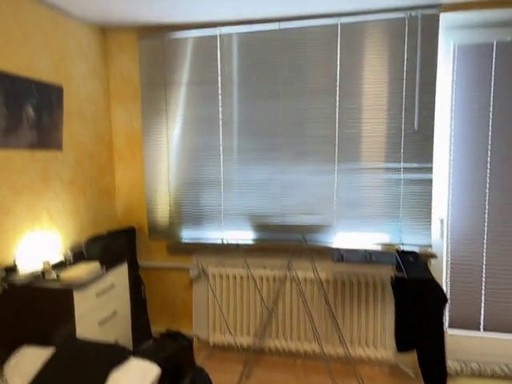
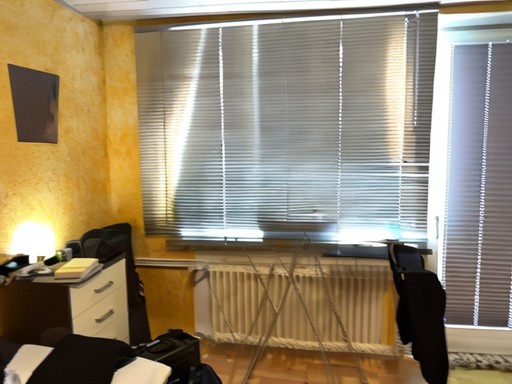
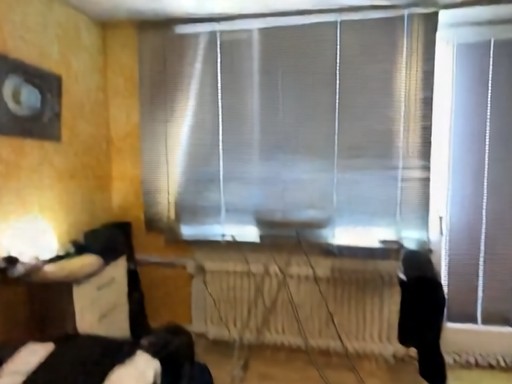
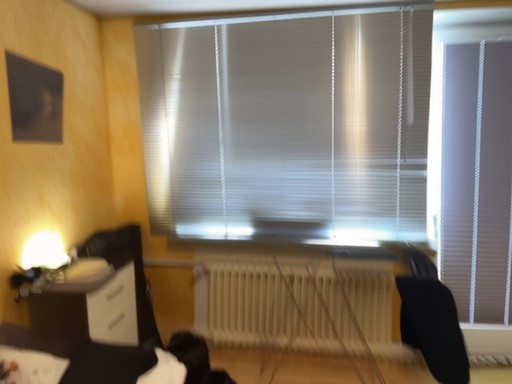
ScanNet++ · 1b75758486
ScanNet++ · dfac5b38df
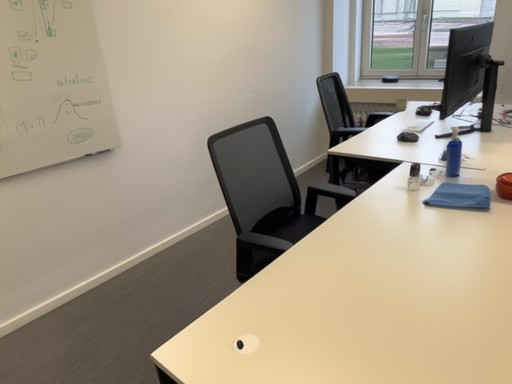
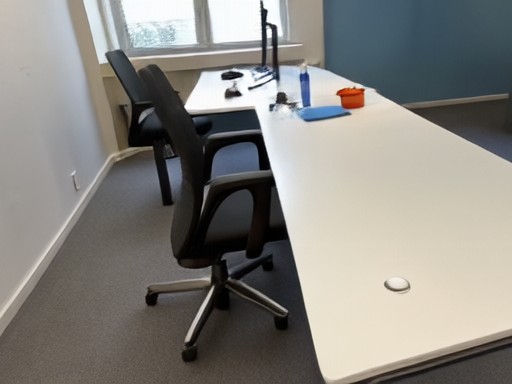
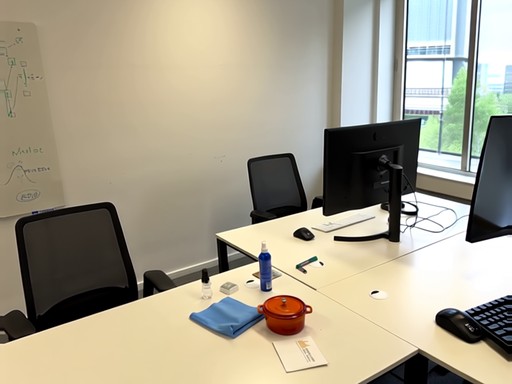
Tanks and Temples · Church
Tanks and Temples · Museum
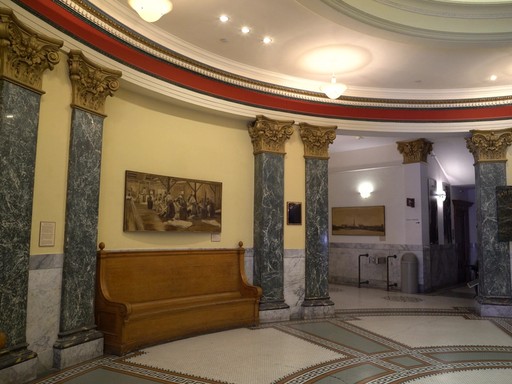
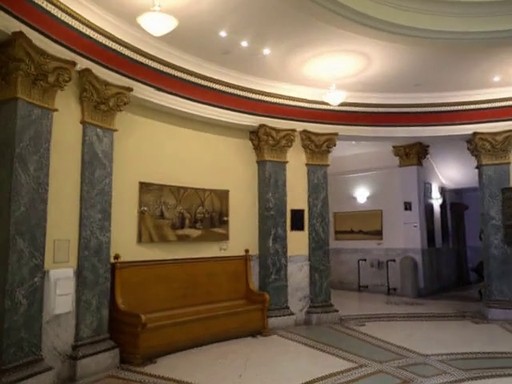
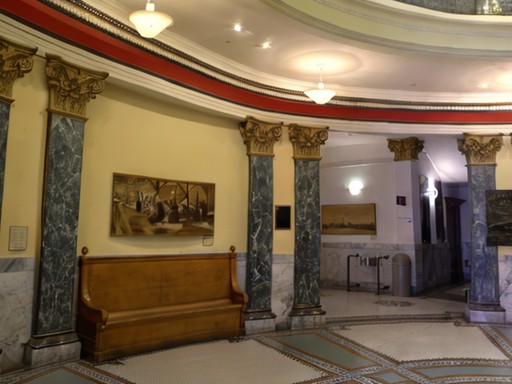
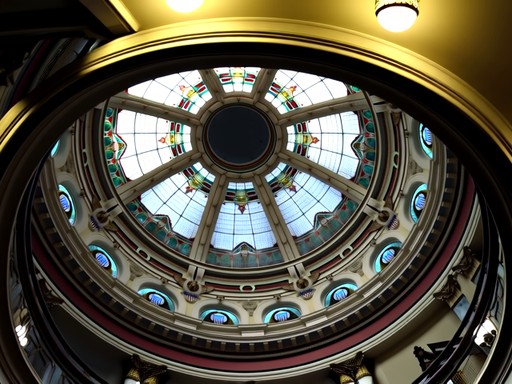
Tanks and Temples · Horse
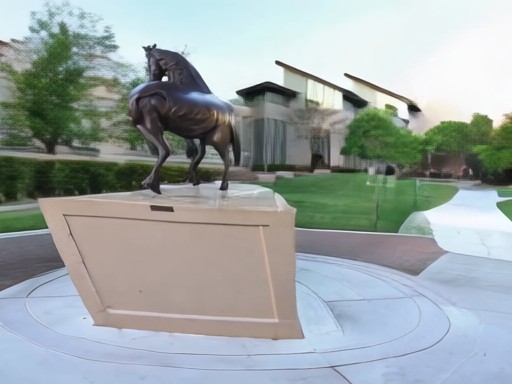
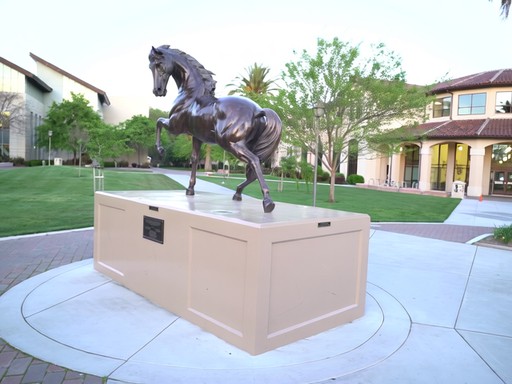
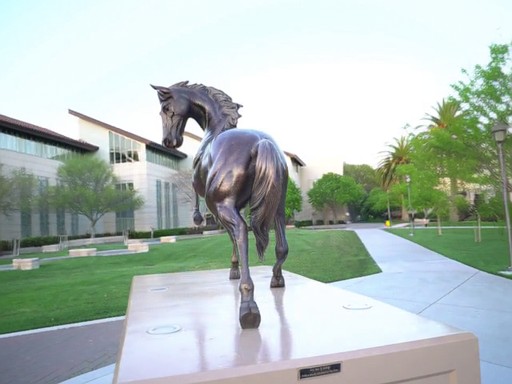
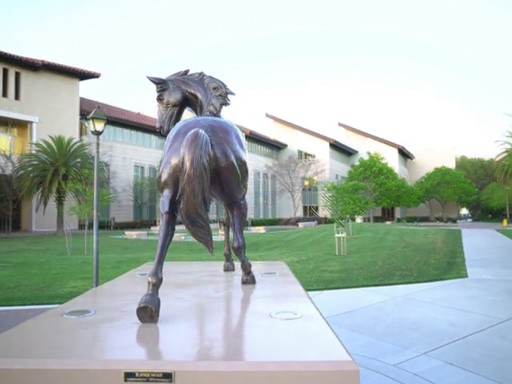
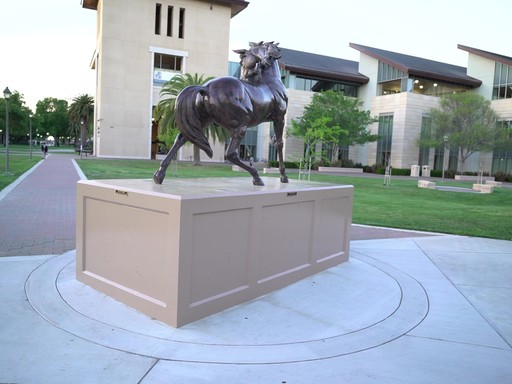
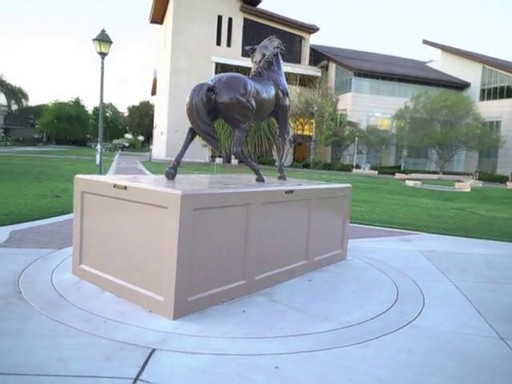
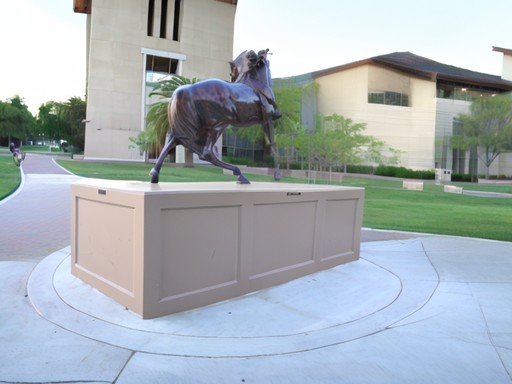
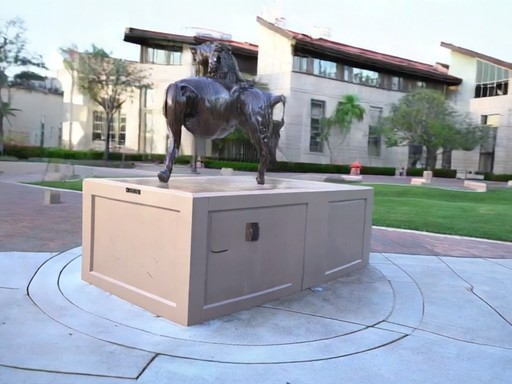
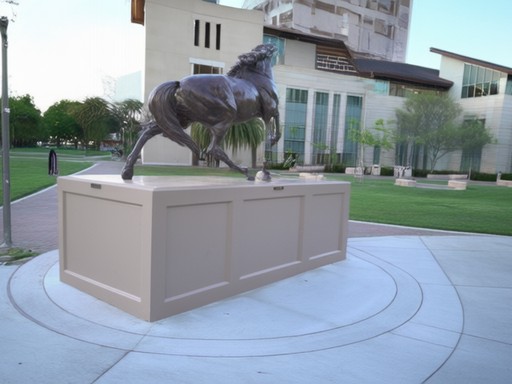
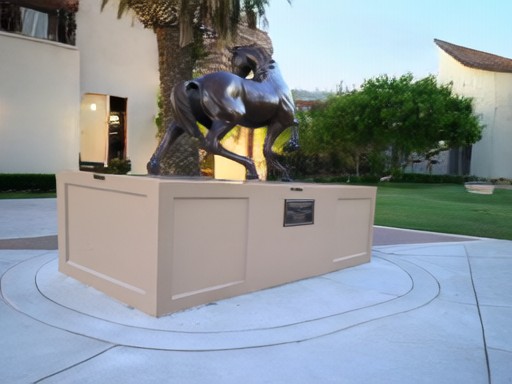
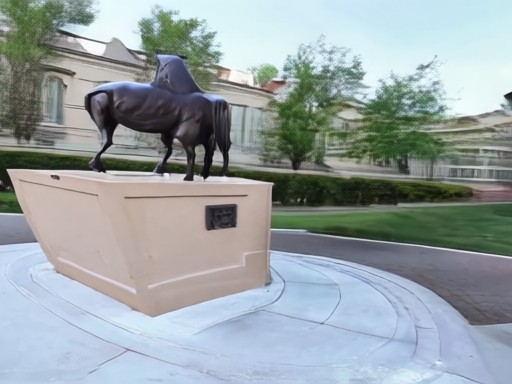
Cases
ScanNet++ · 02455b3d20covisibility 0.92, 2.0 m, 177°
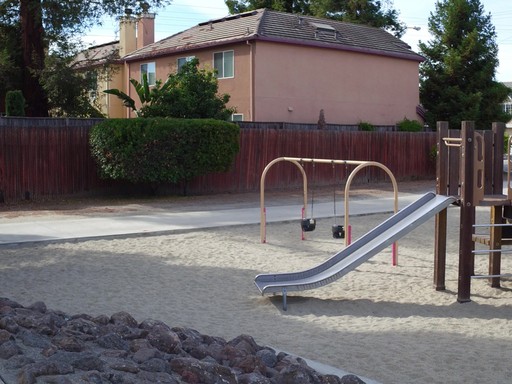
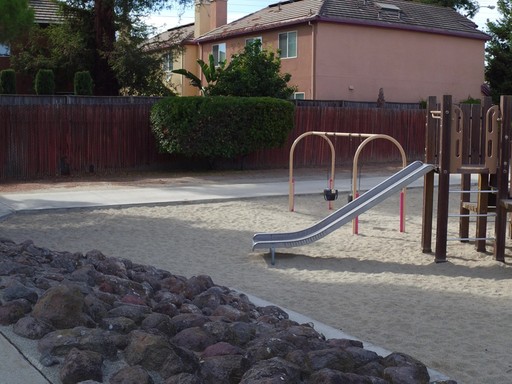
Context views (the first is the trajectory start)
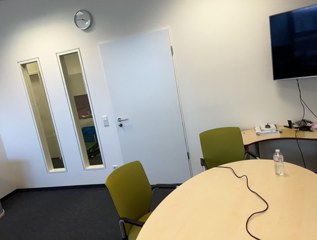
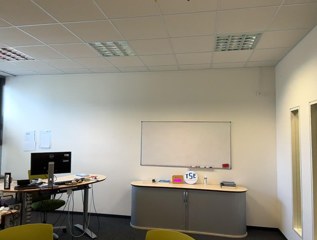
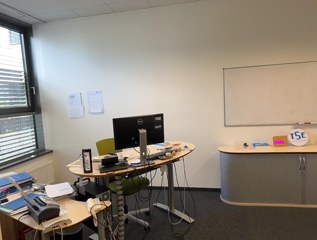
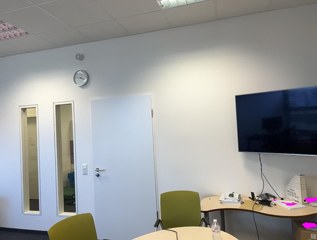
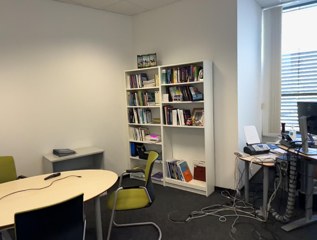
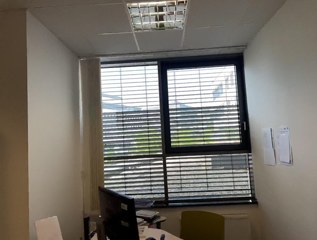
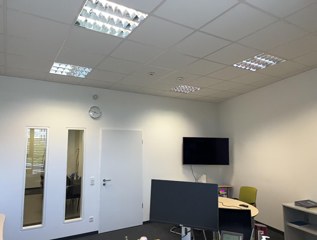
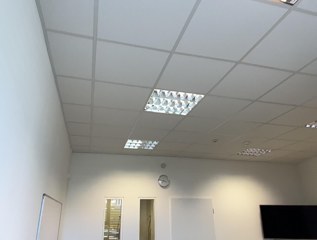
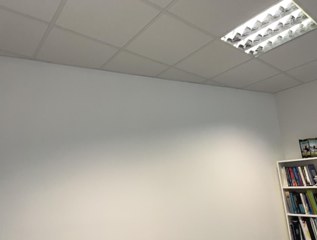
Ground-truth keyframes 0, 3, 6, 9, 12
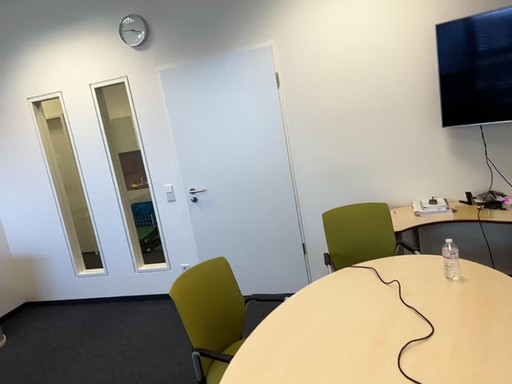
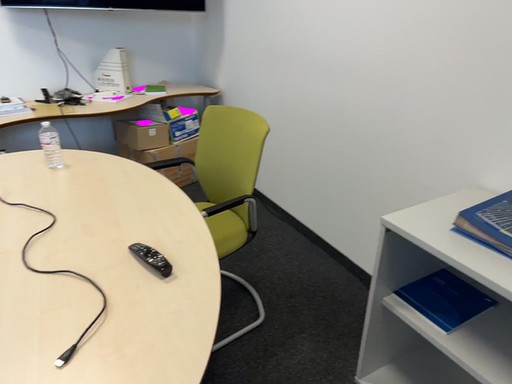
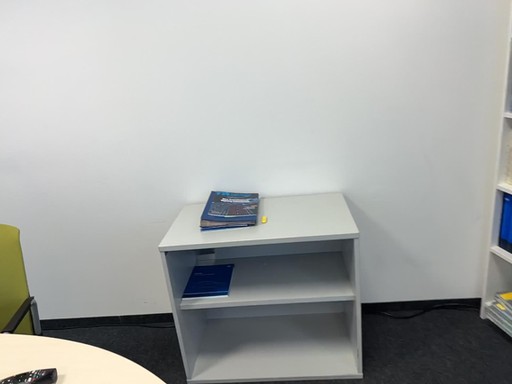
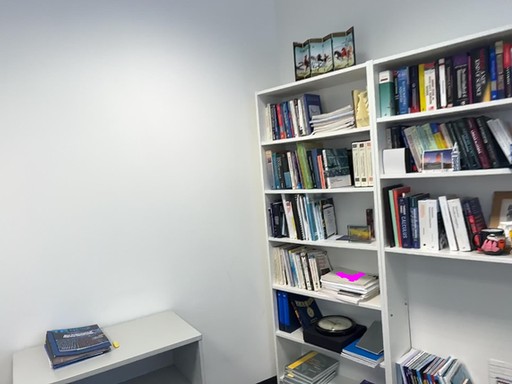
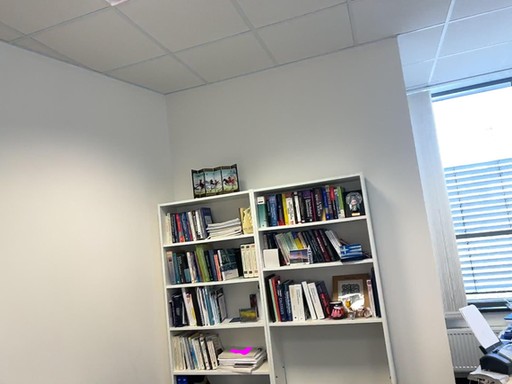
ScanNet++ · 1b75758486covisibility 0.87, 1.1 m, 124°
Context views (the first is the trajectory start)
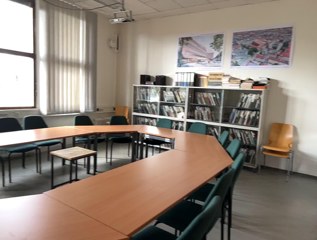
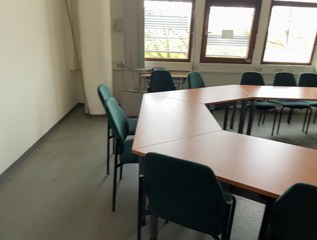
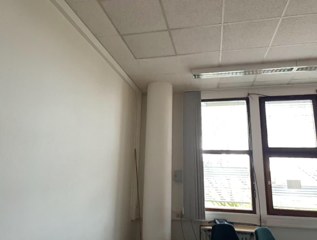
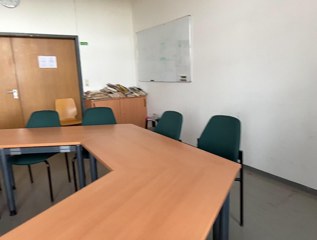
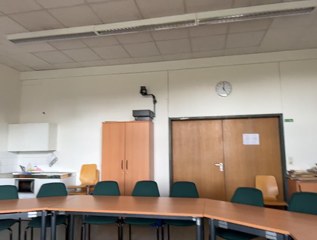
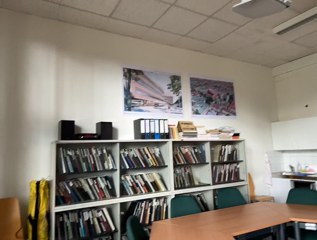
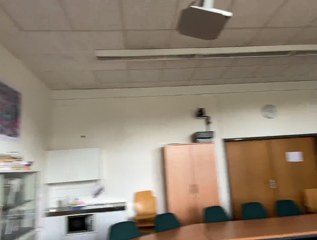
Ground-truth keyframes 0, 3, 6, 9, 12
ScanNet++ · 252652d5bacovisibility 0.95, 1.4 m, 105°
Context views (the first is the trajectory start)
Ground-truth keyframes 0, 3, 6, 9, 12
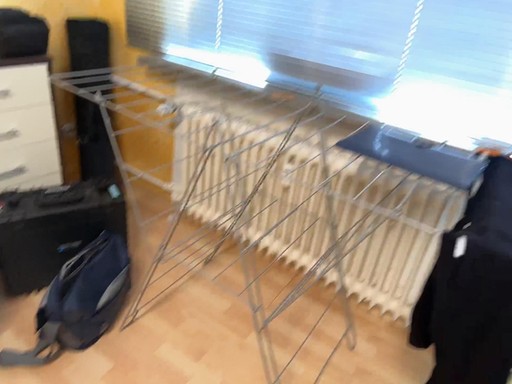
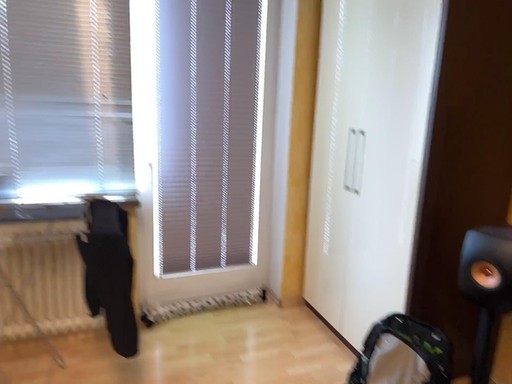
ScanNet++ · 41b00feddbcovisibility 0.90, 2.4 m, 103°
Context views (the first is the trajectory start)
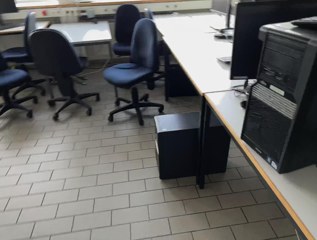
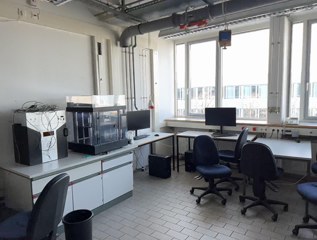
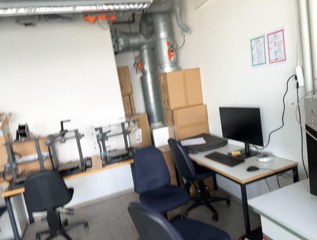
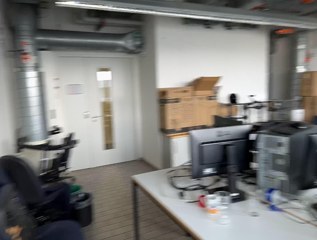
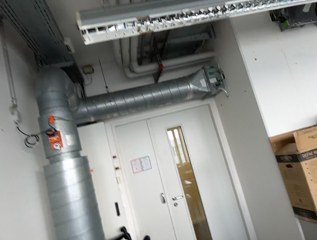
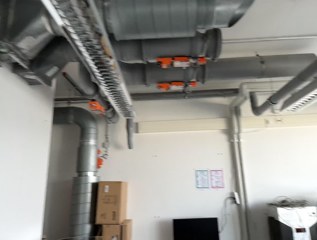
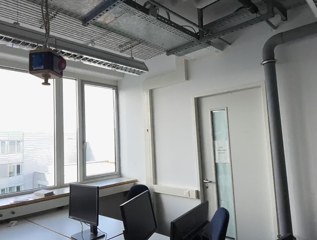
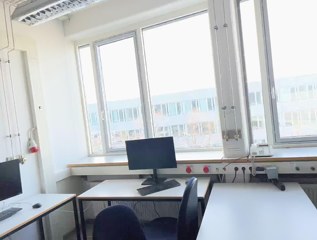
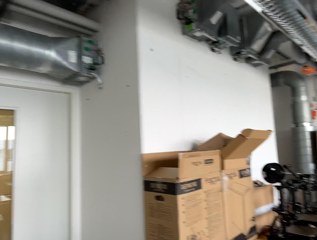
Ground-truth keyframes 0, 3, 6, 9, 12
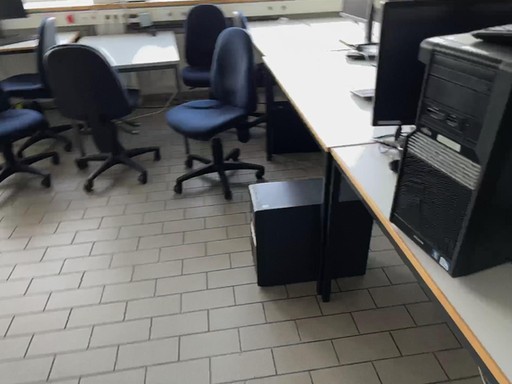
ScanNet++ · 5eb31827b7covisibility 0.84, 1.0 m, 179°
Context views (the first is the trajectory start)
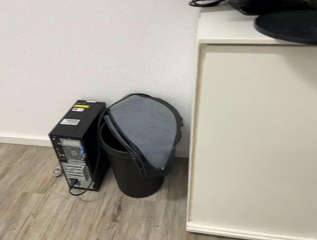
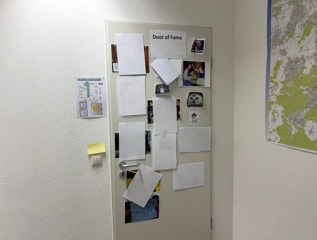
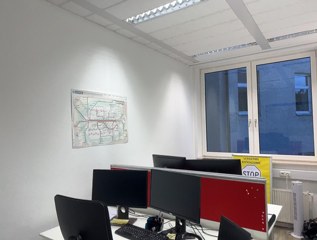
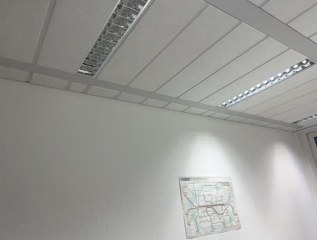
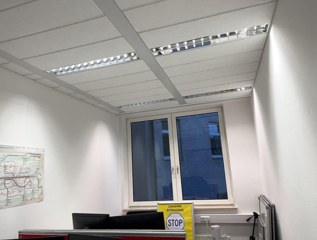
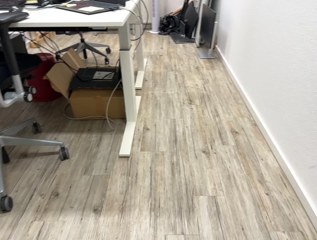
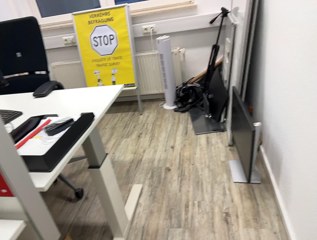
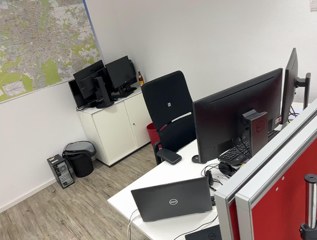
Ground-truth keyframes 0, 3, 6, 9, 12
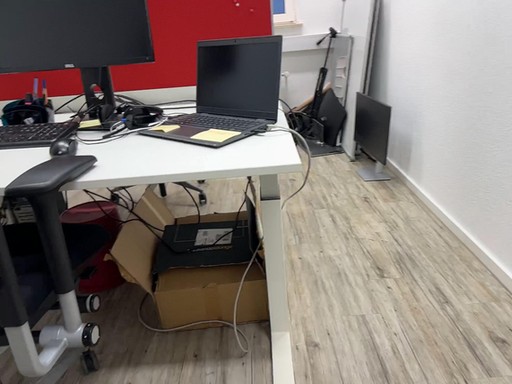
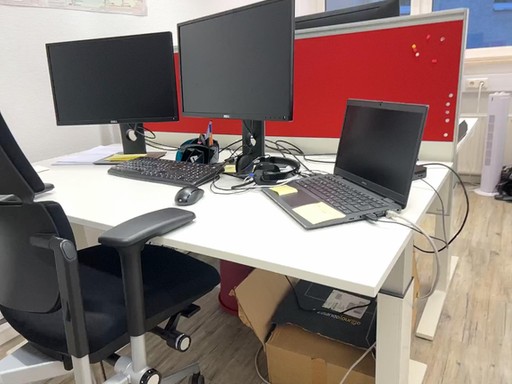
ScanNet++ · 824d9cfa6ecovisibility 0.94, 1.5 m, 84°
Context views (the first is the trajectory start)
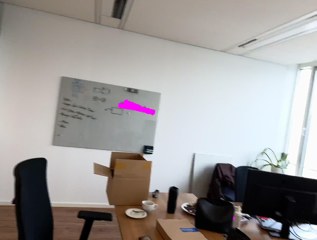
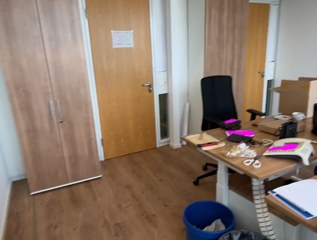
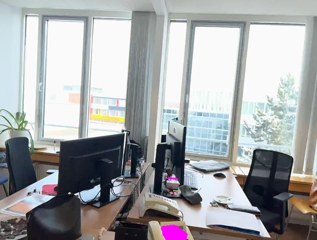
Ground-truth keyframes 0, 3, 6, 9, 12
ScanNet++ · 8e00ac7f59covisibility 0.85, 2.3 m, 88°
Context views (the first is the trajectory start)
Ground-truth keyframes 0, 3, 6, 9, 12
ScanNet++ · a24f64f7fbcovisibility 1.00, 1.0 m, 48°
Context views (the first is the trajectory start)
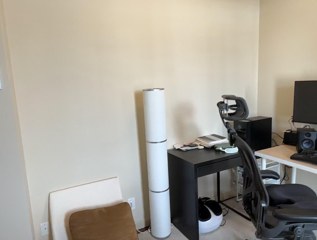
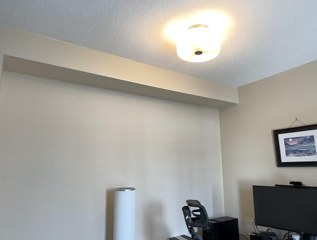
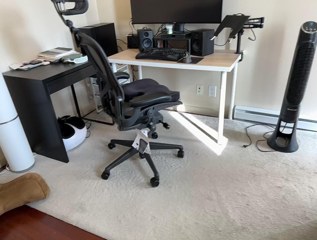
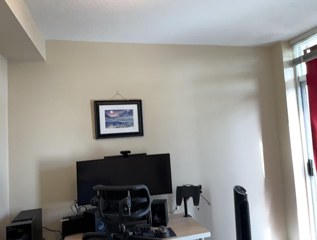
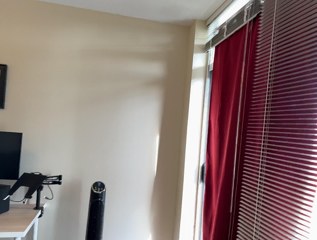
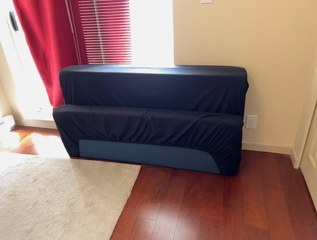
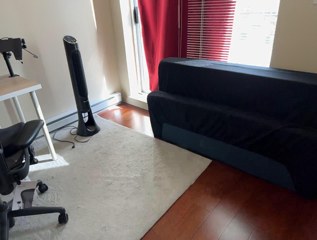
Ground-truth keyframes 0, 3, 6, 9, 12
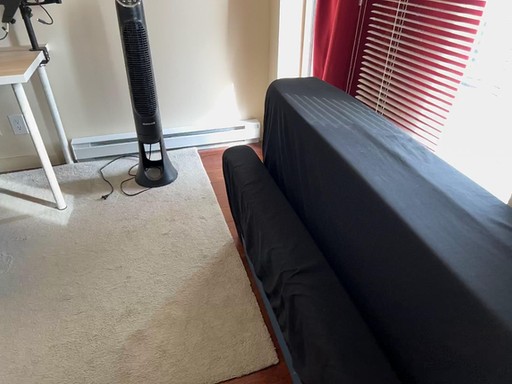
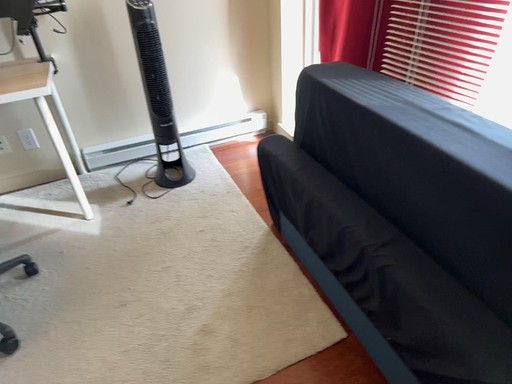
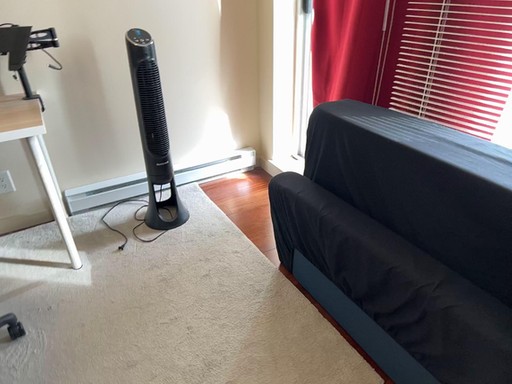
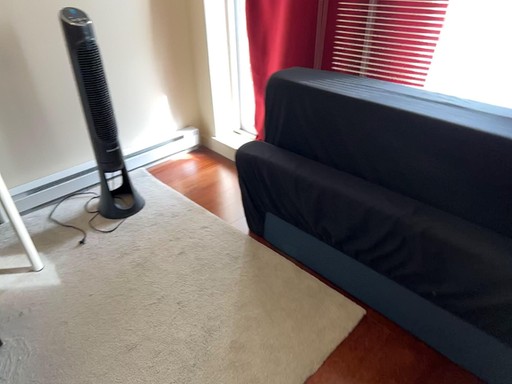
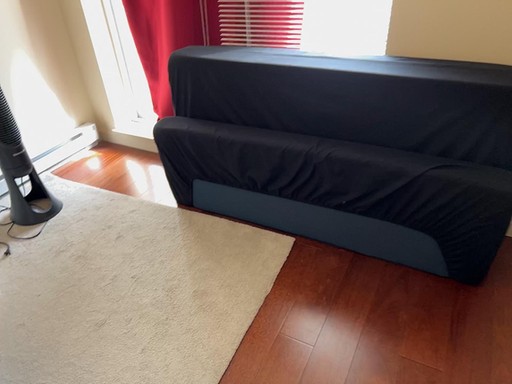
ScanNet++ · bc400d86e1covisibility 0.87, 2.1 m, 173°
Context views (the first is the trajectory start)
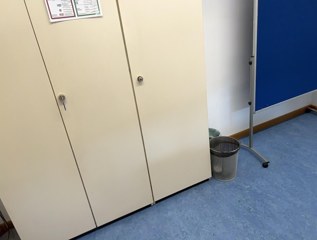
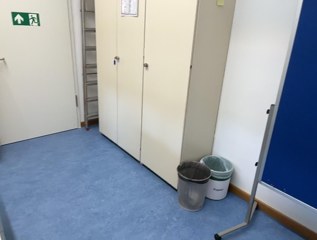
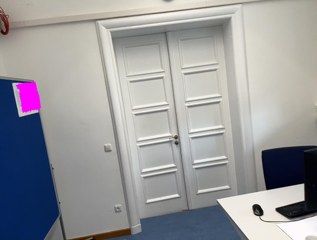
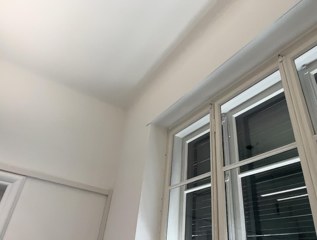
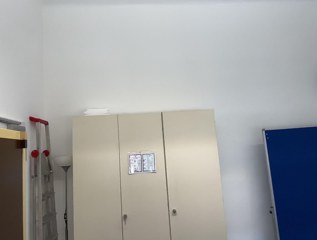
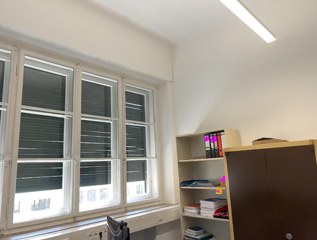
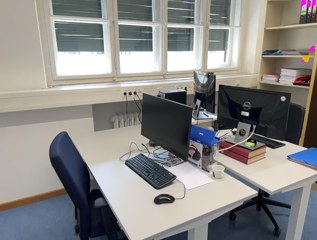
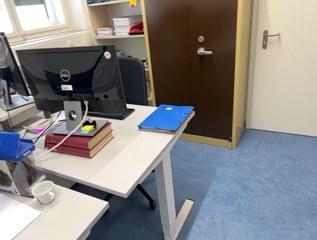
Ground-truth keyframes 0, 3, 6, 9, 12
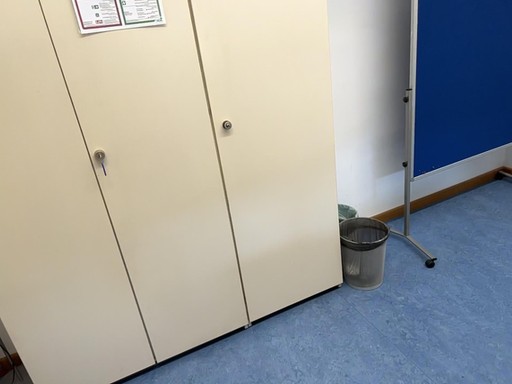
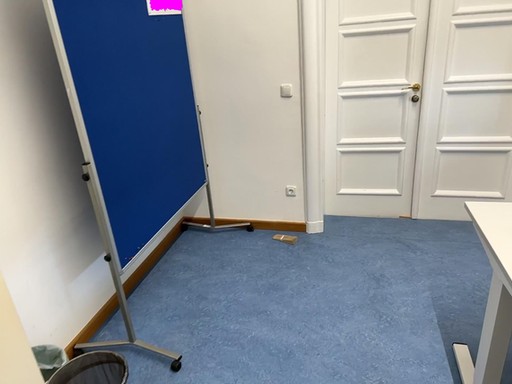
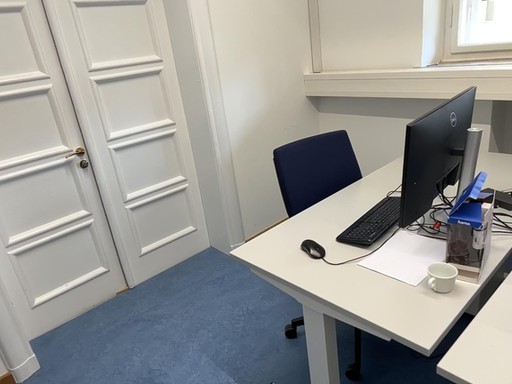
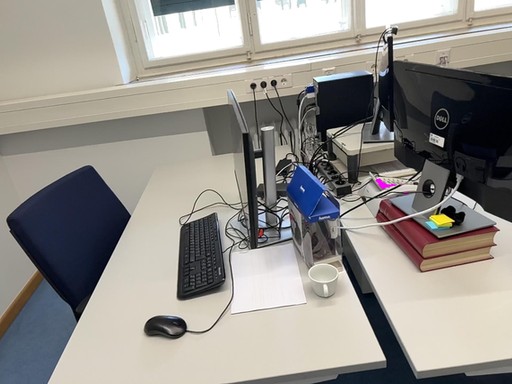
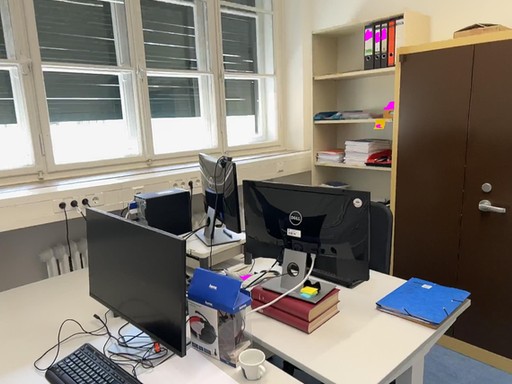
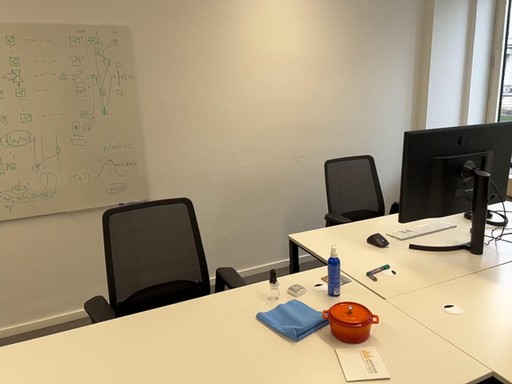
ScanNet++ · dfac5b38dfcovisibility 0.90, 2.0 m, 72°
Context views (the first is the trajectory start)
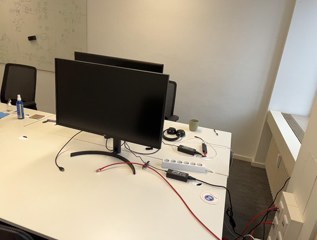
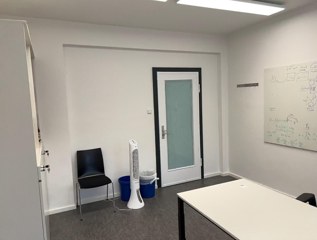
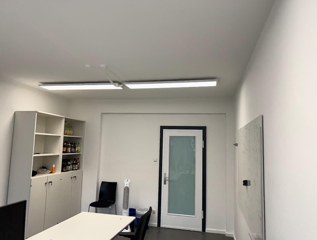
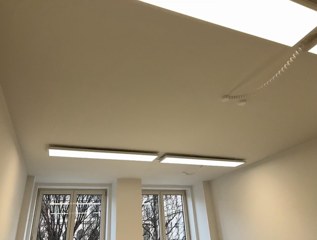
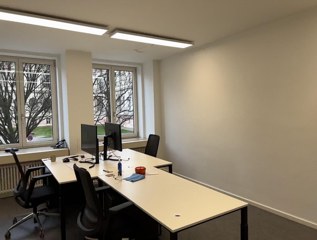
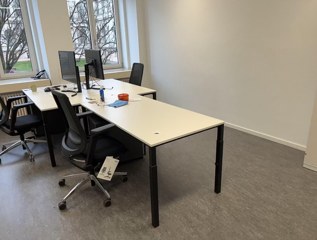
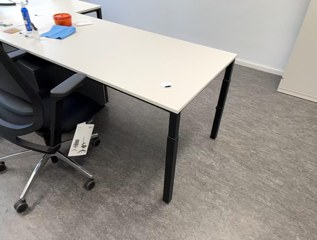
Ground-truth keyframes 0, 3, 6, 9, 12
Tanks and Temples · Ballroom · third trajectorycovisibility 0.96, 3.1 m, 117°
Context views (the first is the trajectory start)
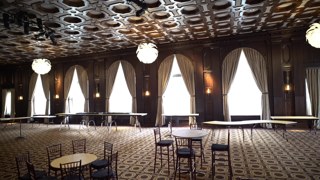
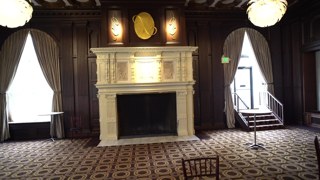
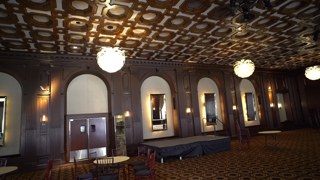
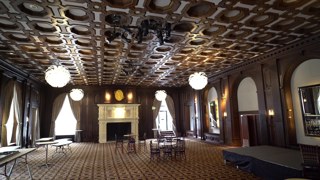
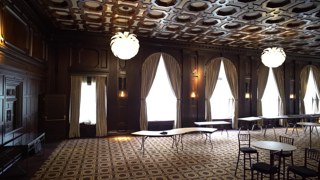
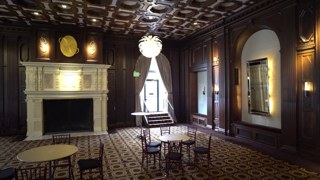
Ground-truth keyframes 0, 3, 6, 9, 12
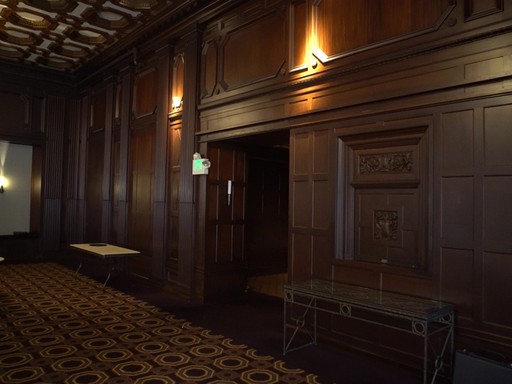
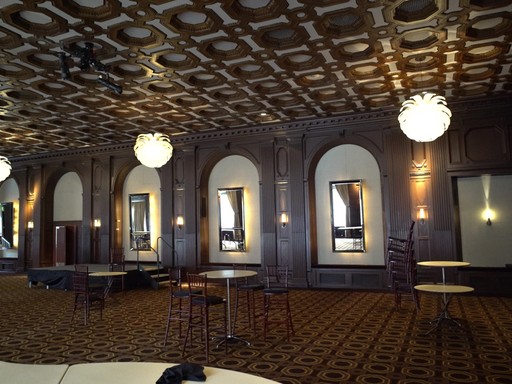
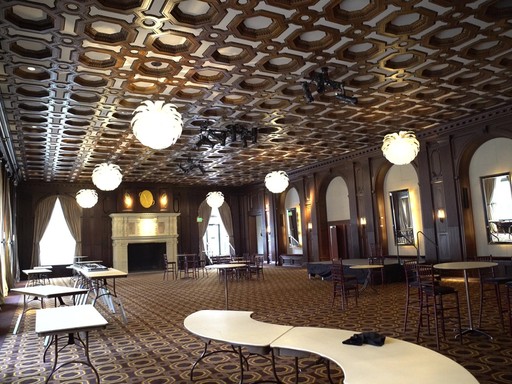
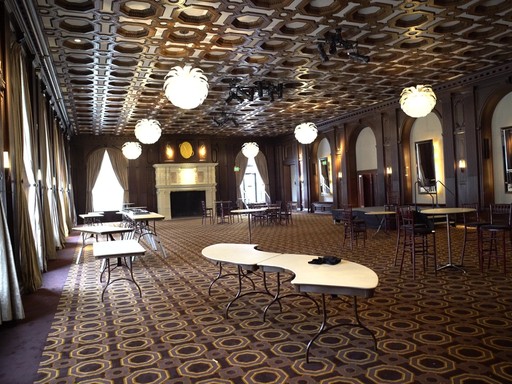
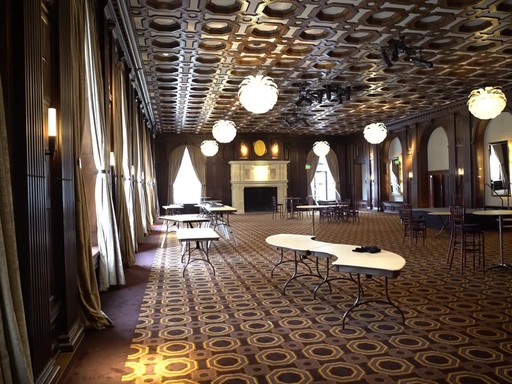
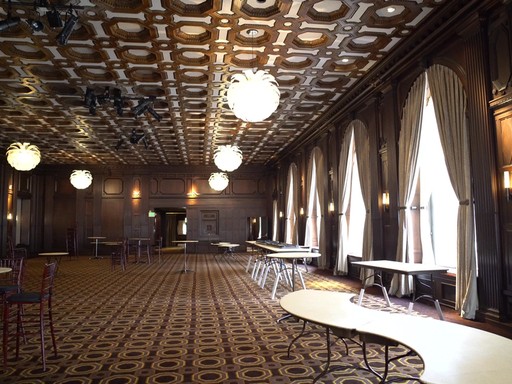
Tanks and Temples · Ballroom · fourth trajectorycovisibility 0.97, 4.1 m, 25°
Context views (the first is the trajectory start)
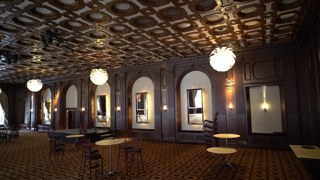
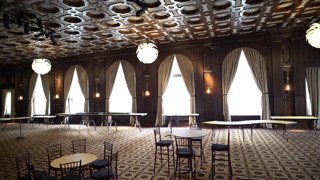
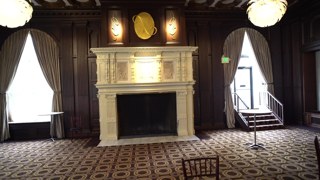
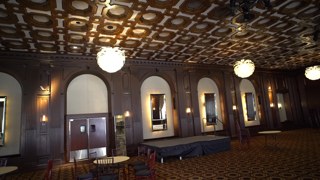
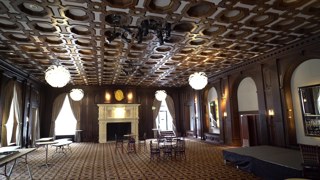
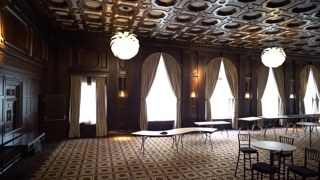
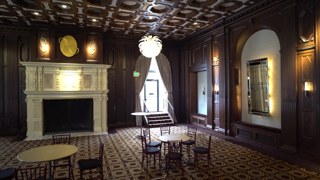
Ground-truth keyframes 0, 3, 6, 9, 12
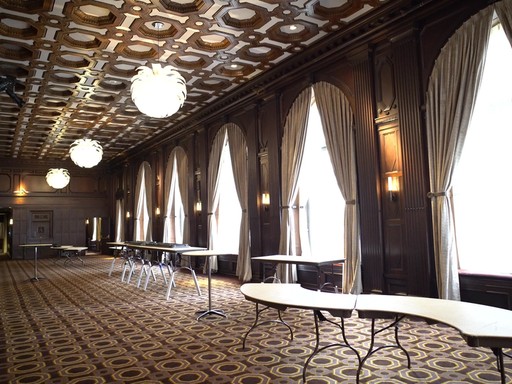
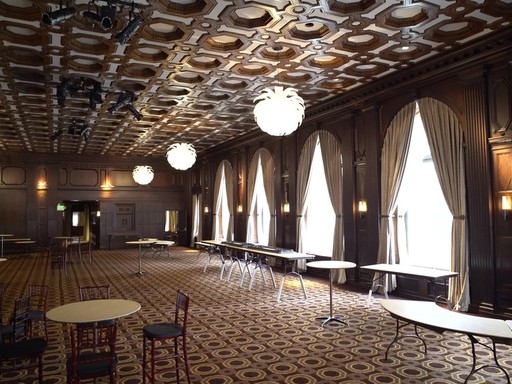
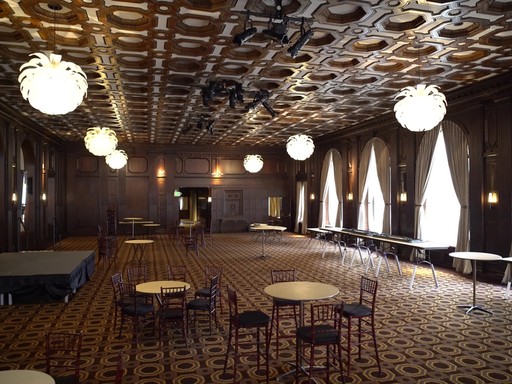
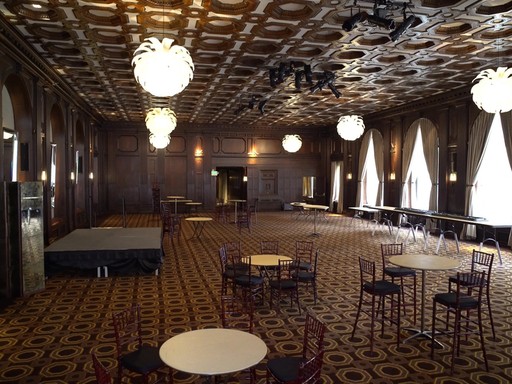
Tanks and Temples · Church · third trajectorycovisibility 0.94, 4.6 m, 34°
Context views (the first is the trajectory start)
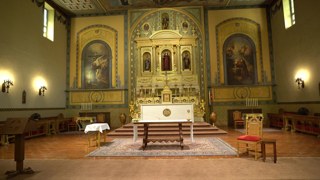
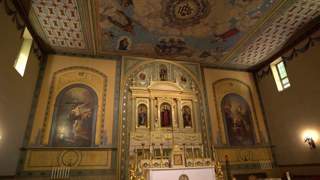
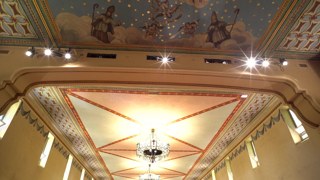
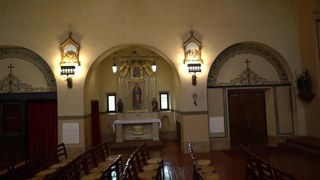
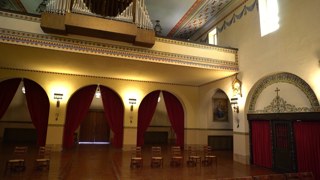
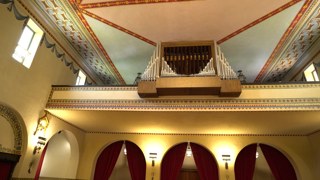
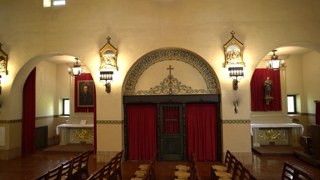
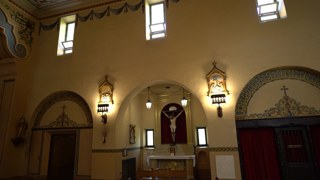
Ground-truth keyframes 0, 3, 6, 9, 12
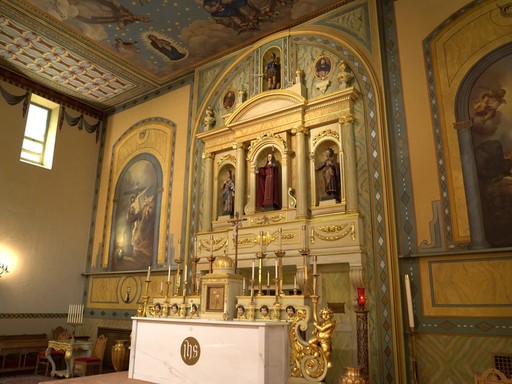
Tanks and Temples · Church · fourth trajectorycovisibility 0.92, 3.5 m, 113°
Context views (the first is the trajectory start)
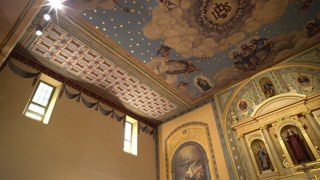
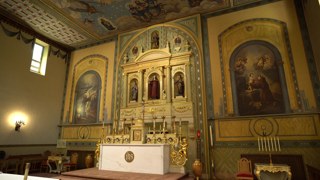
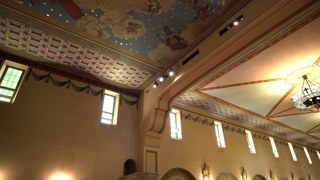
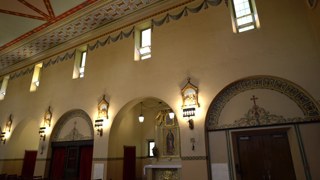
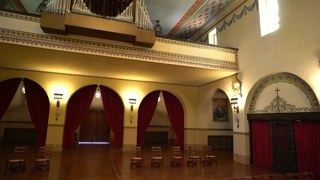
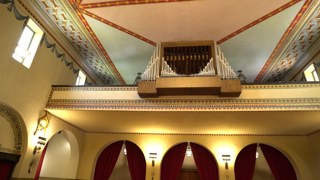
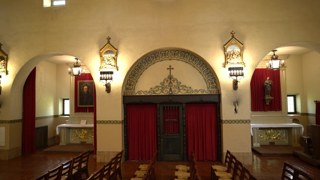
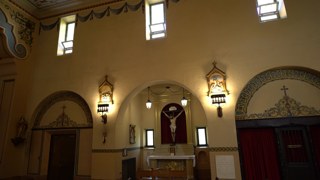
Ground-truth keyframes 0, 3, 6, 9, 12
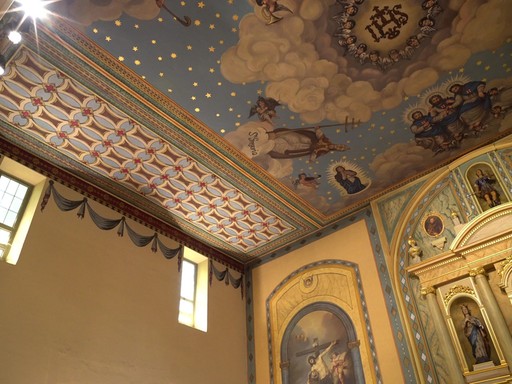
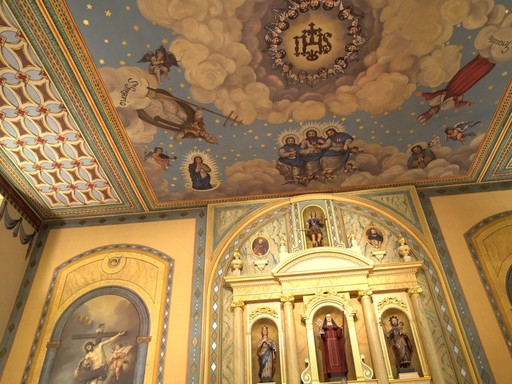
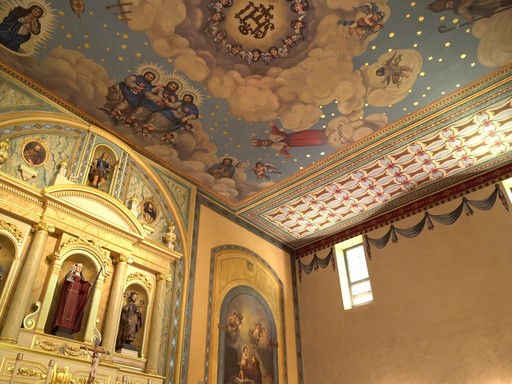
Tanks and Temples · Courtroom · third trajectorycovisibility 0.92, 2.5 m, 86°
Context views (the first is the trajectory start)
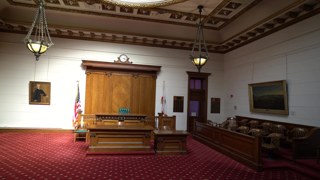
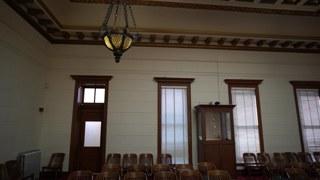
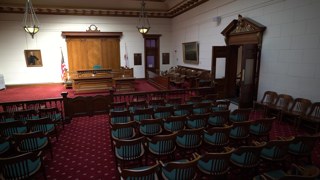
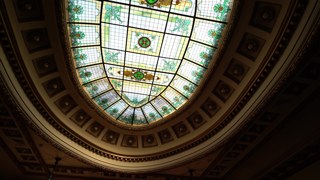
Ground-truth keyframes 0, 3, 6, 9, 12
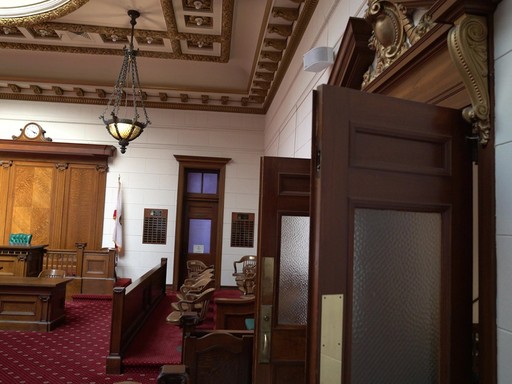
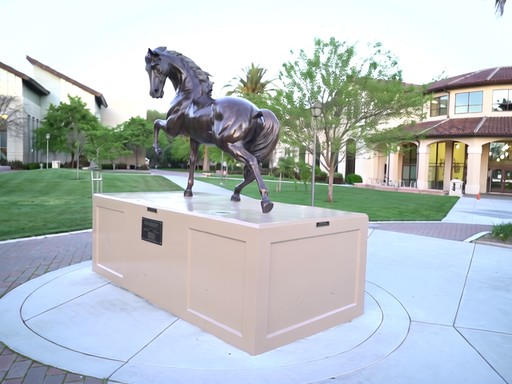
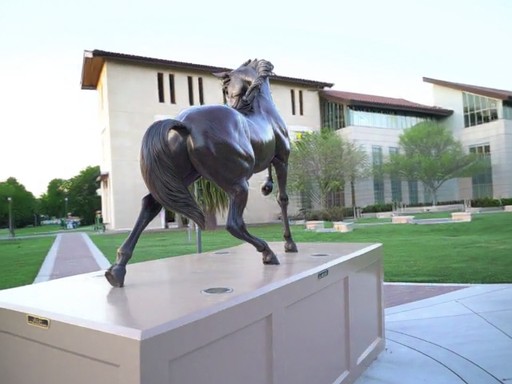
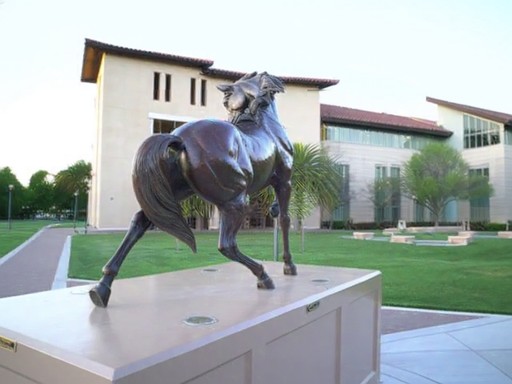
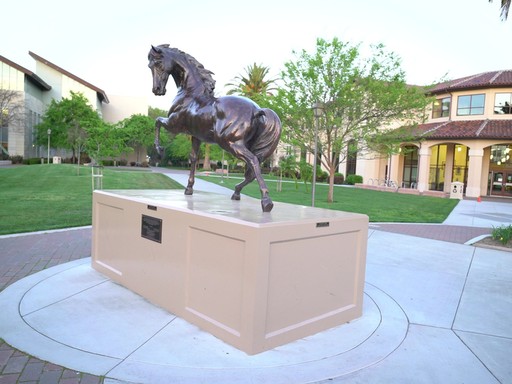
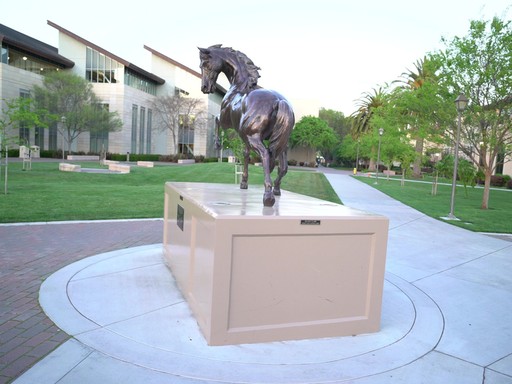
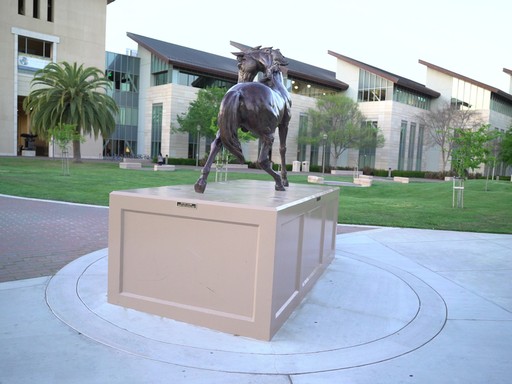
Tanks and Temples · Horsecovisibility 0.85, 4.2 m, 81°
Context views (the first is the trajectory start)
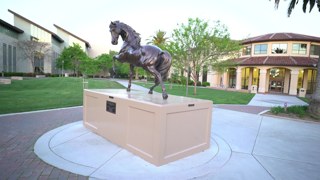
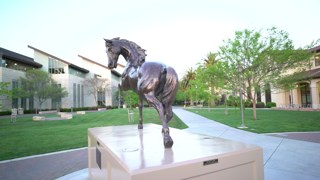
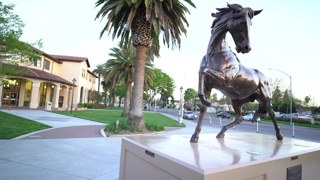
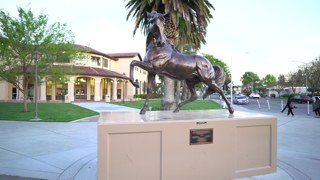
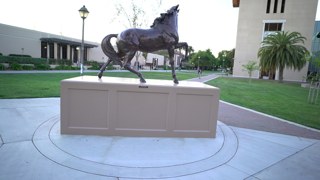
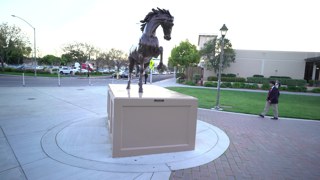
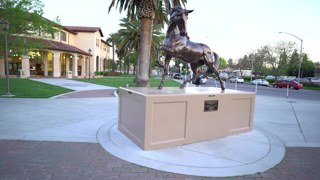
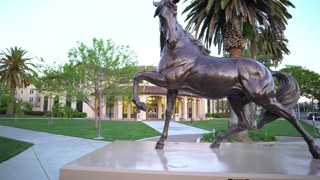
Ground-truth keyframes 0, 3, 6, 9, 12
Tanks and Temples · Meetingroo · third trajectorycovisibility 0.93, 4.5 m, 91°
Context views (the first is the trajectory start)
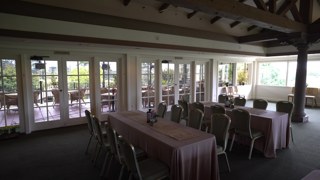
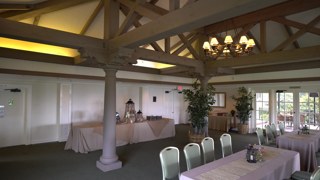
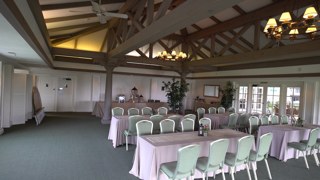
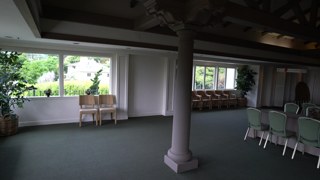
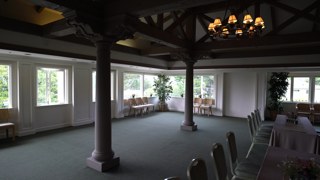
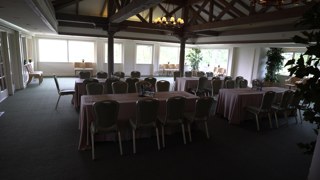
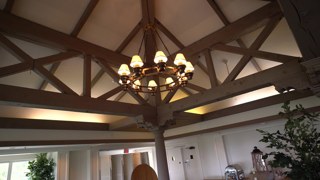
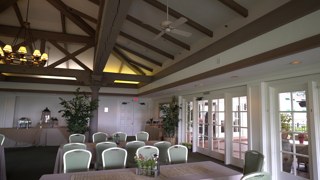
Ground-truth keyframes 0, 3, 6, 9, 12
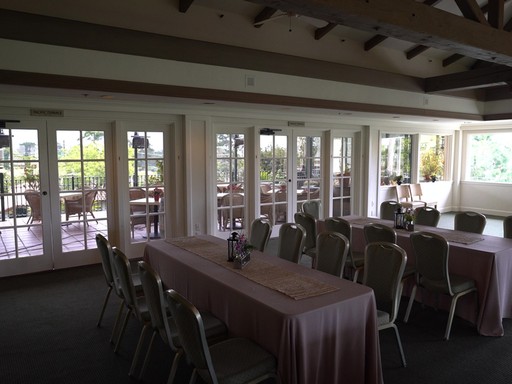
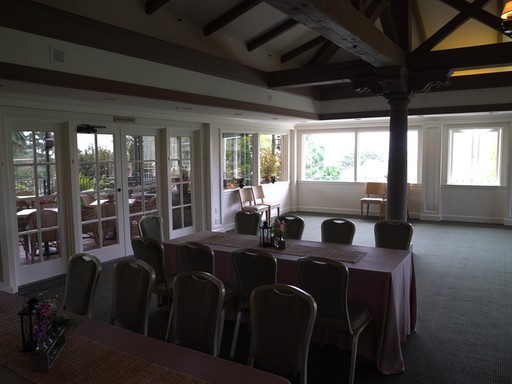
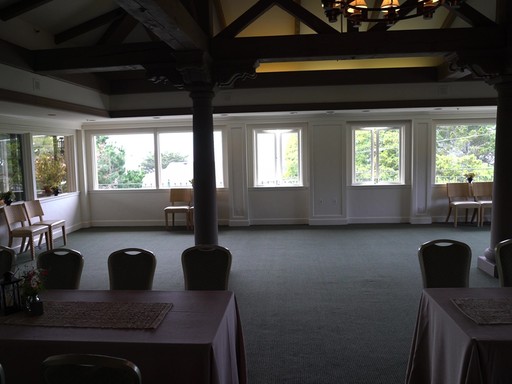
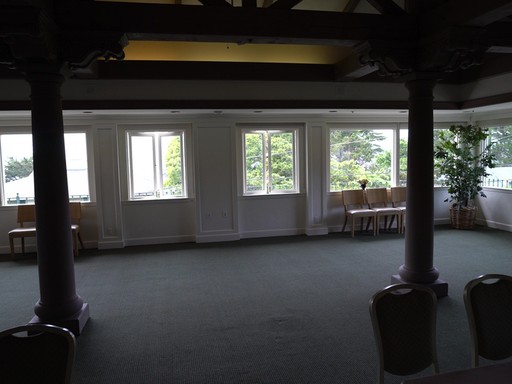
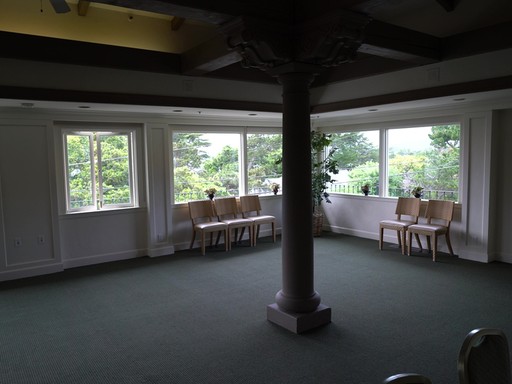
Tanks and Temples · Museum · second trajectorycovisibility 0.89, 3.0 m, 125°
Context views (the first is the trajectory start)
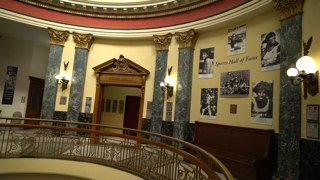
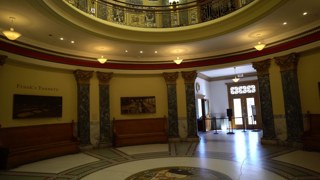
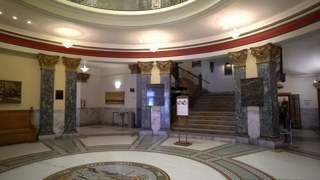
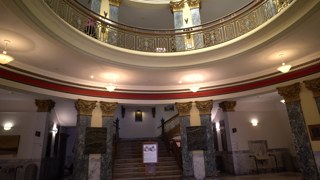
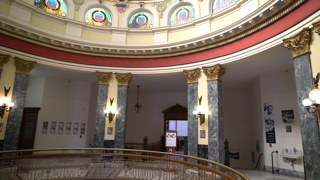
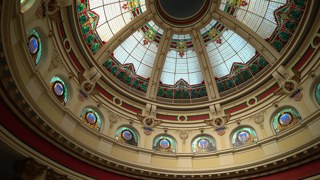
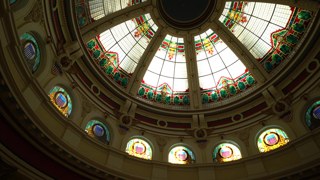
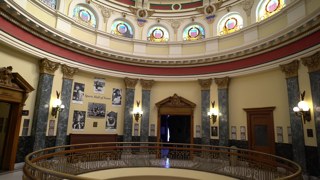
Ground-truth keyframes 0, 3, 6, 9, 12
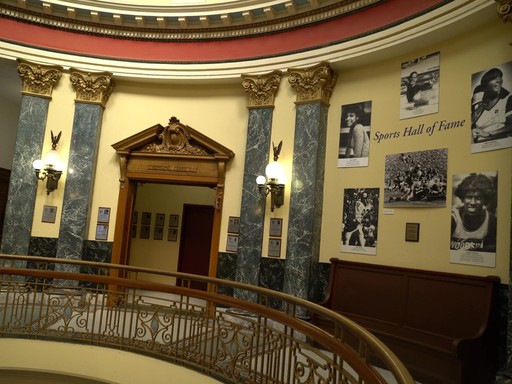
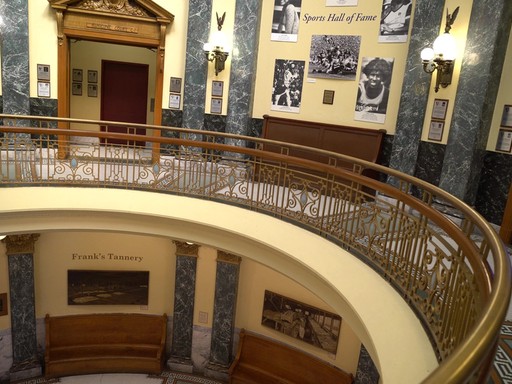
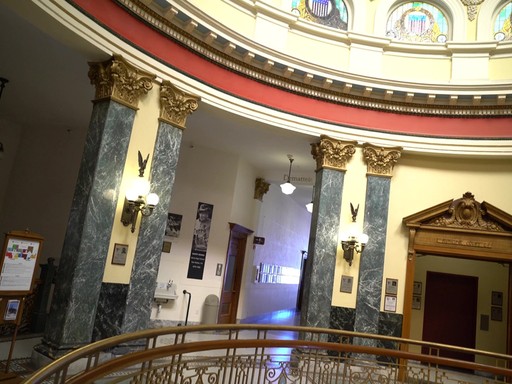
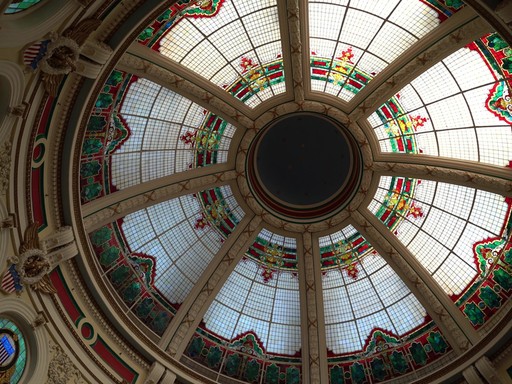
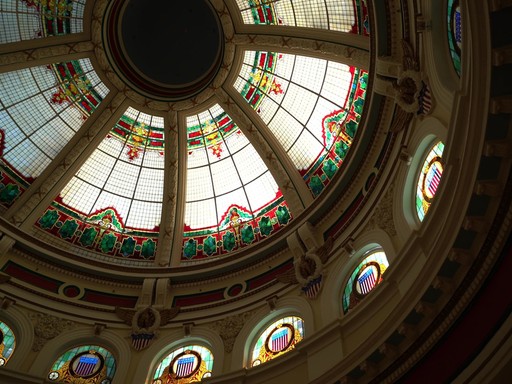
Tanks and Temples · Museum · third trajectorycovisibility 0.86, 2.0 m, 110°
Context views (the first is the trajectory start)
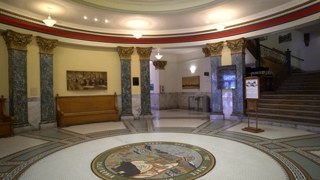
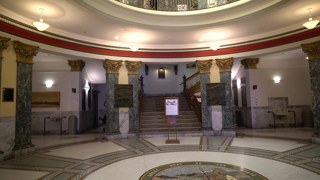
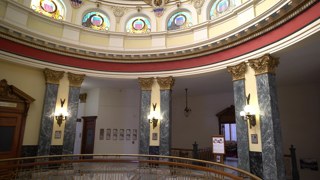
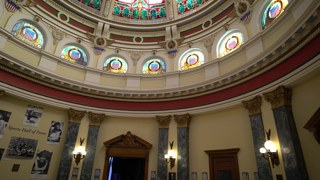
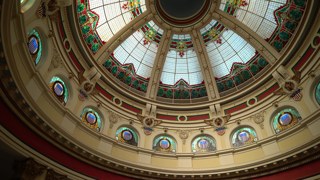
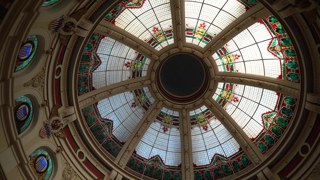
Ground-truth keyframes 0, 3, 6, 9, 12
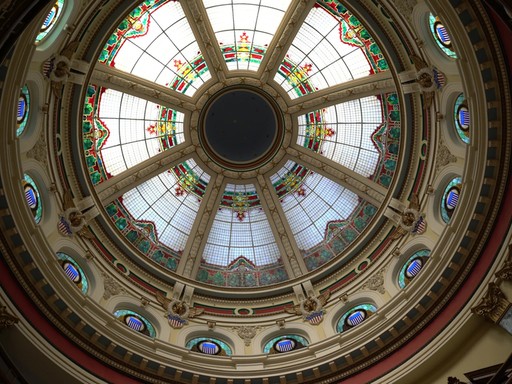
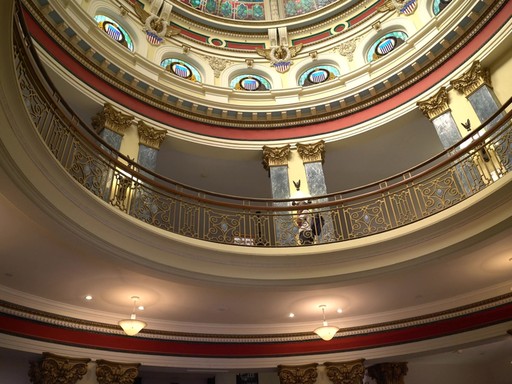
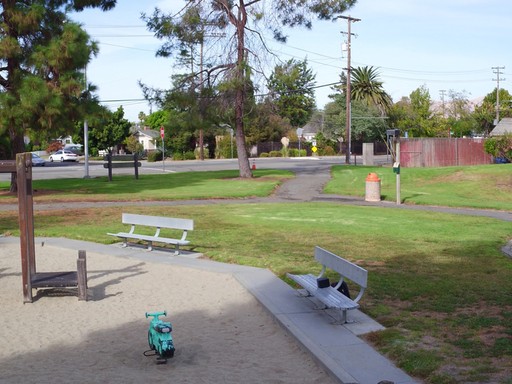
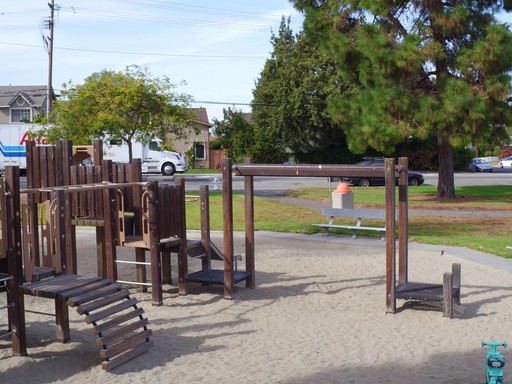
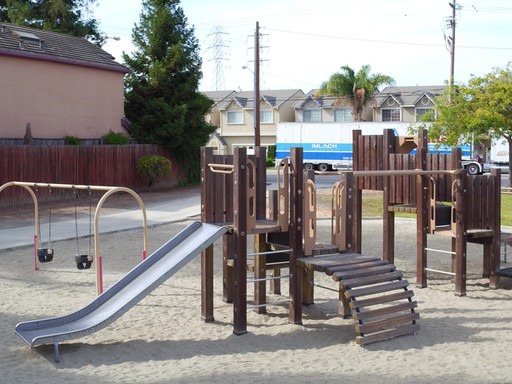
Tanks and Temples · Playground · second trajectorycovisibility 0.87, 4.1 m, 100°
Context views (the first is the trajectory start)
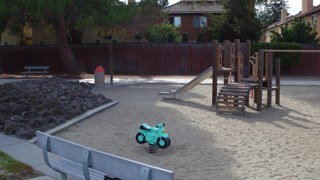
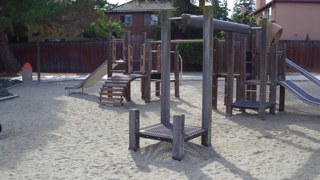
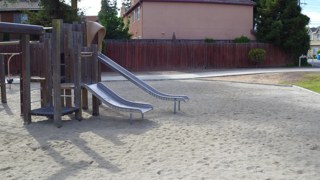
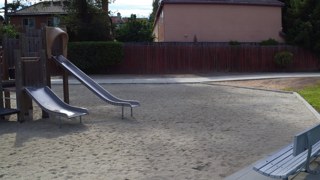
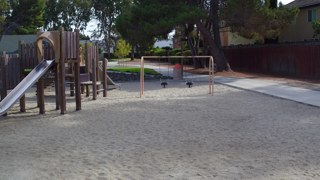
Ground-truth keyframes 0, 3, 6, 9, 12
Further Tanks and Temples cases
The other candidate trajectories of the Tanks and Temples scenes, evaluated with the same protocol for Mundo and the three strongest baselines and not part of the results above: Auditorium (second trajectory), Courtroom (second trajectory), Francis, Lighthouse, M60, Meetingroom (fourth trajectory), Museum, Panther.
Tanks and Temples · Auditorium · second trajectorycovisibility 0.90, 2.9 m, 179°
Context views (the first is the trajectory start)
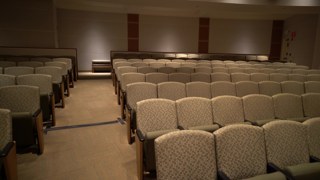
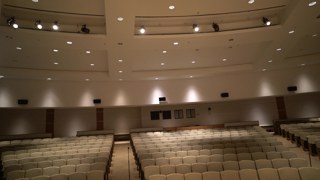
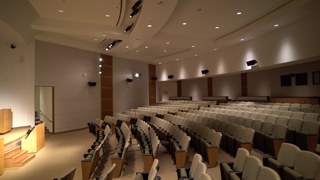
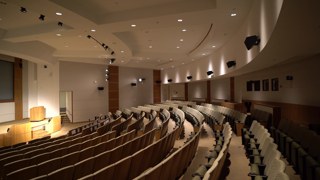
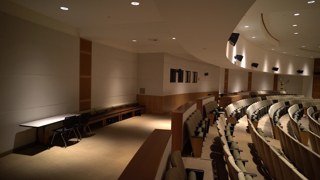
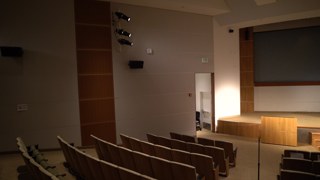
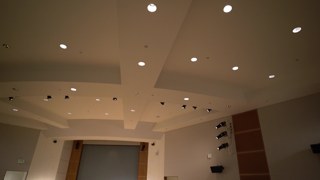
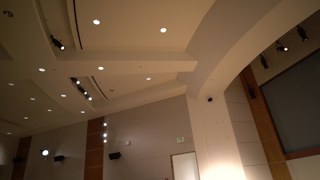
Ground-truth keyframes 0, 3, 6, 9, 12
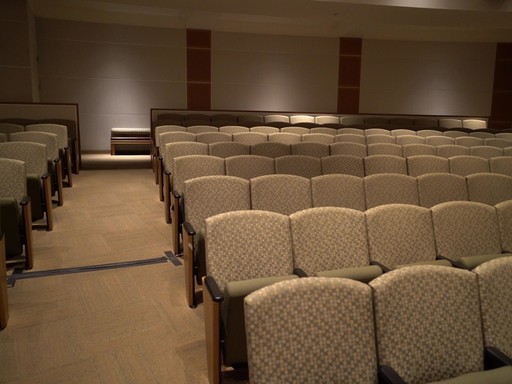
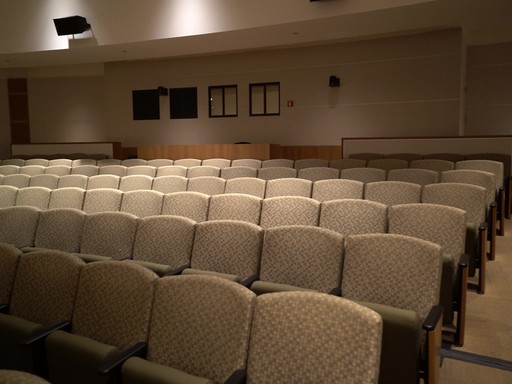
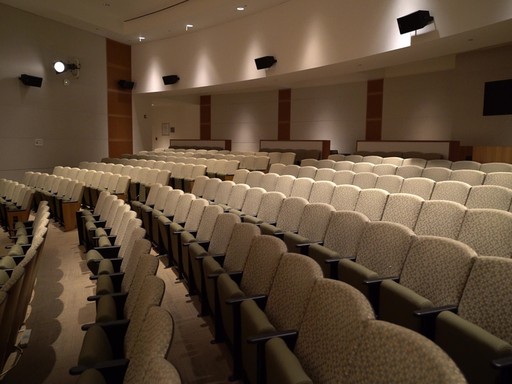
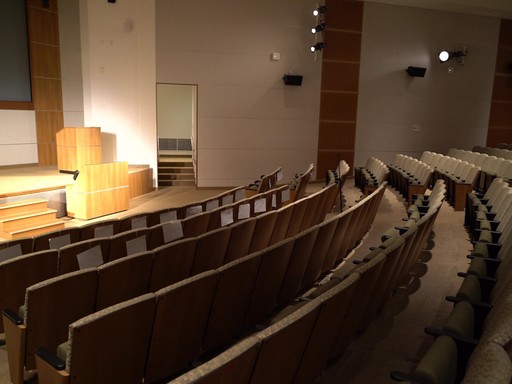
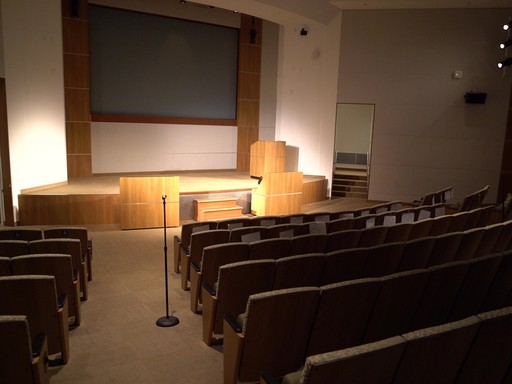
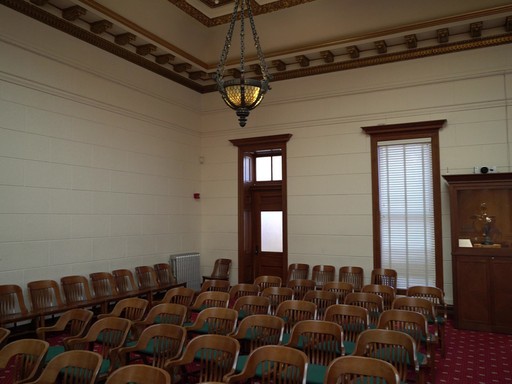
Tanks and Temples · Courtroom · second trajectorycovisibility 0.90, 3.1 m, 164°
Context views (the first is the trajectory start)
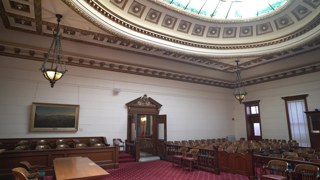
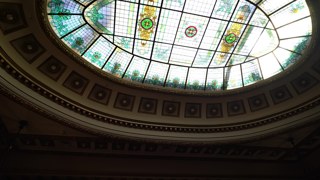
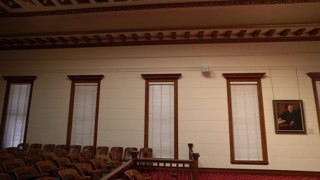
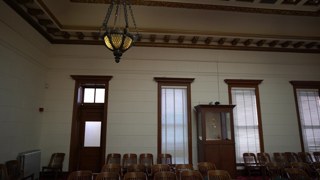
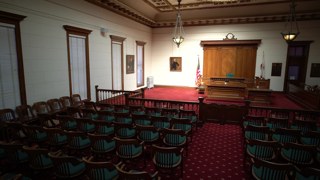
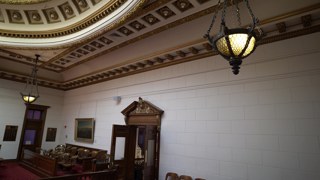
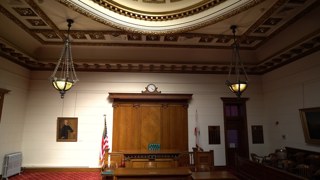
Ground-truth keyframes 0, 3, 6, 9, 12
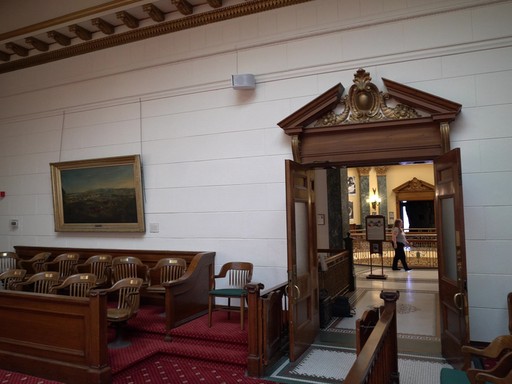
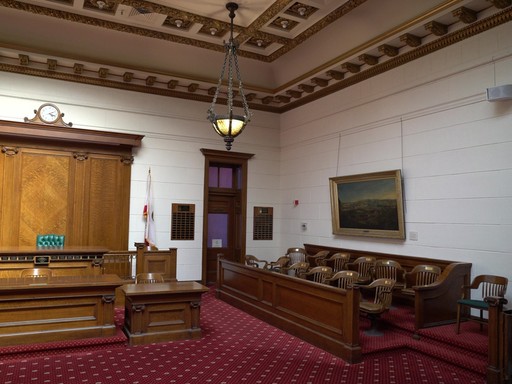
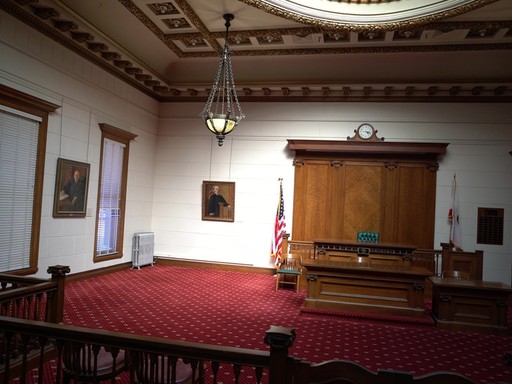
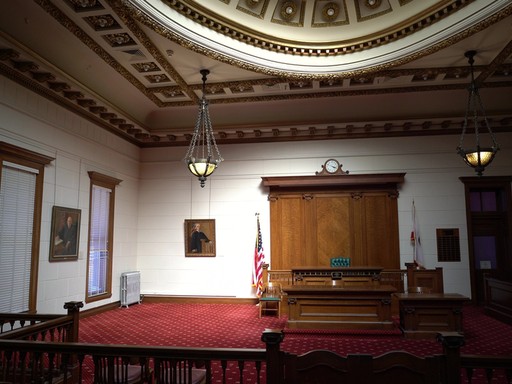
Tanks and Temples · Franciscovisibility 0.88, 2.4 m, 48°
Context views (the first is the trajectory start)
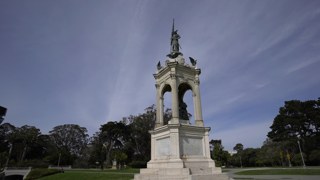
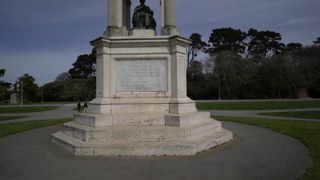
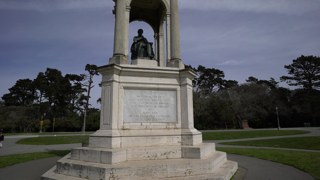
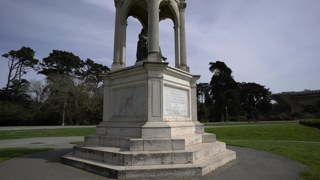
Ground-truth keyframes 0, 3, 6, 9, 12
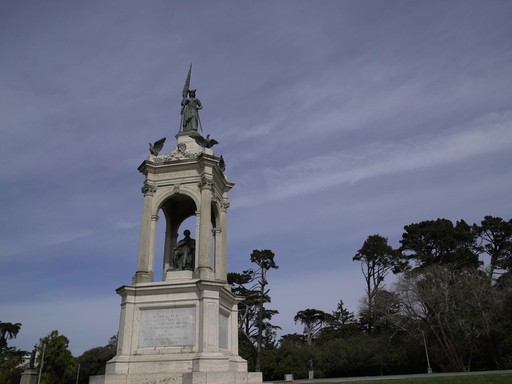
Tanks and Temples · Lighthousecovisibility 0.86, 4.2 m, 75°
Context views (the first is the trajectory start)
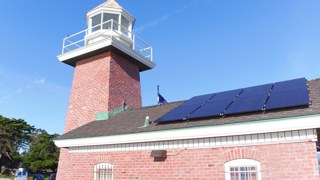
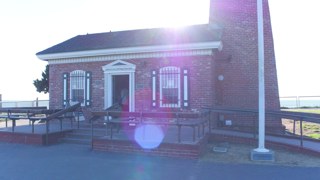
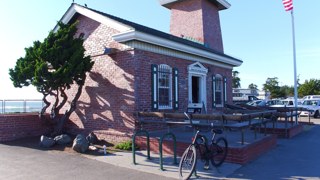
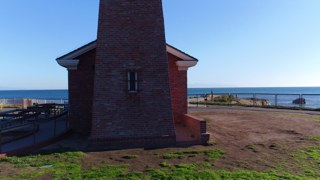
Ground-truth keyframes 0, 3, 6, 9, 12
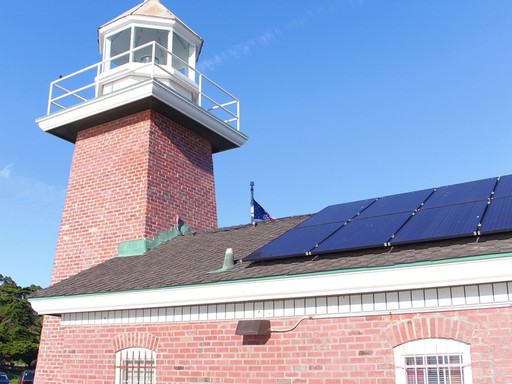
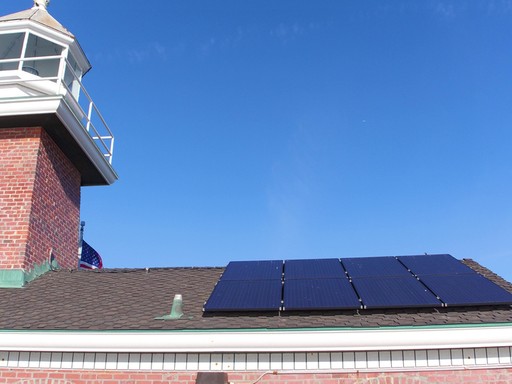
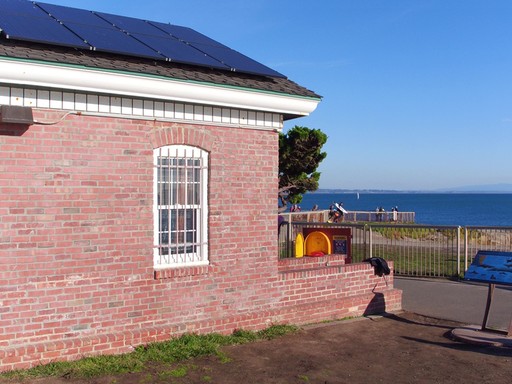
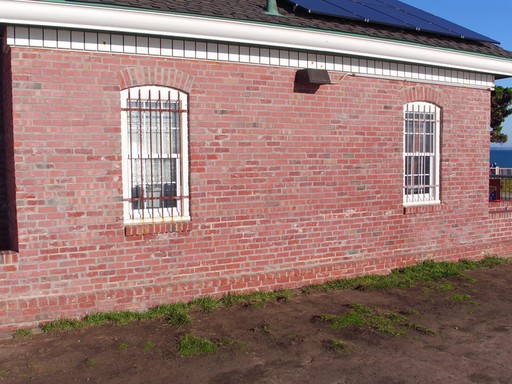
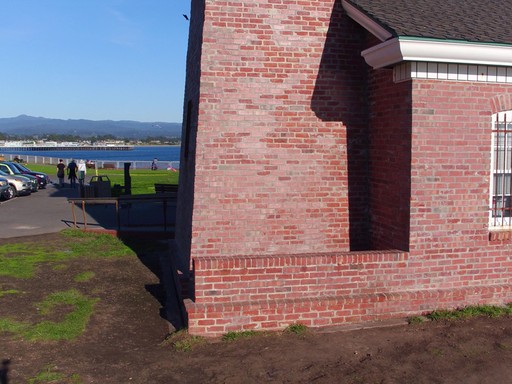
Tanks and Temples · M60covisibility 0.93, 4.2 m, 39°
Context views (the first is the trajectory start)
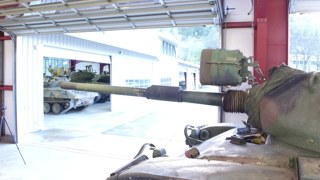
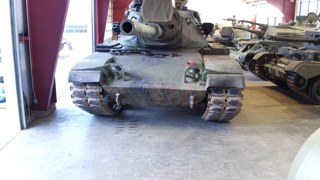
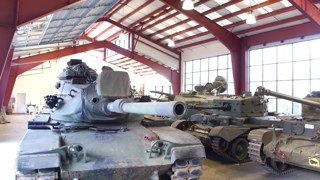
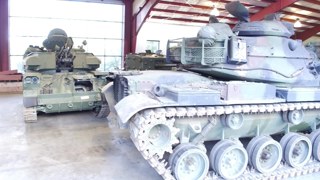
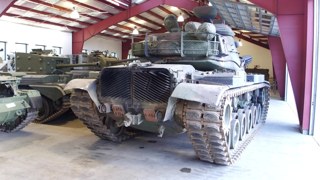
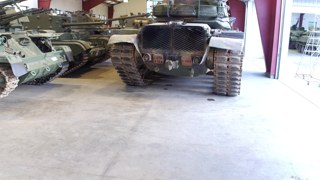
Ground-truth keyframes 0, 3, 6, 9, 12
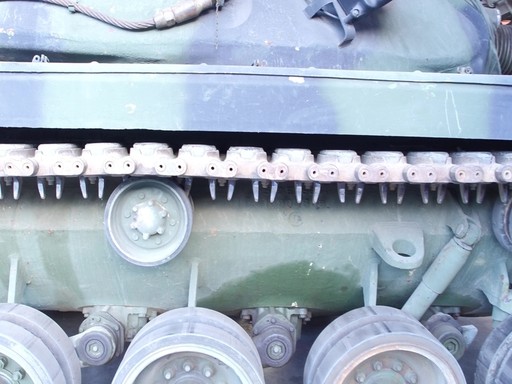
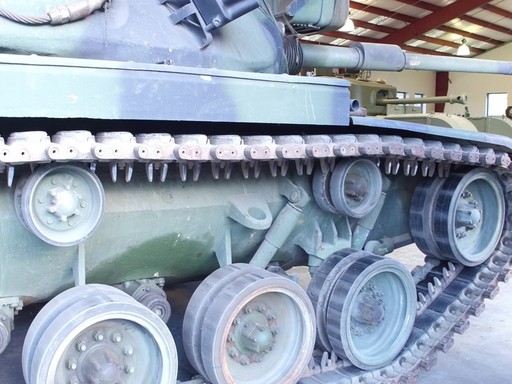
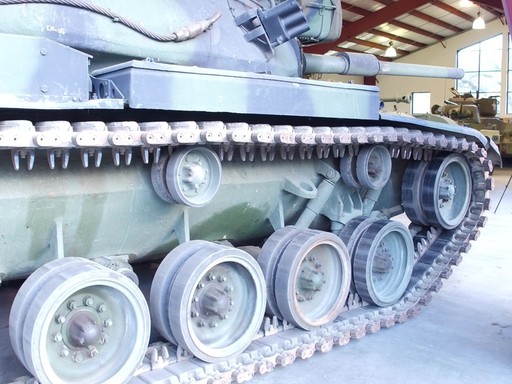
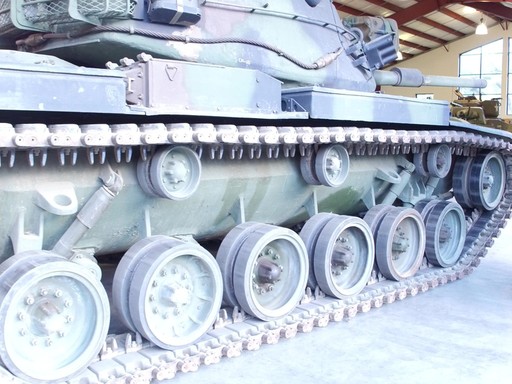
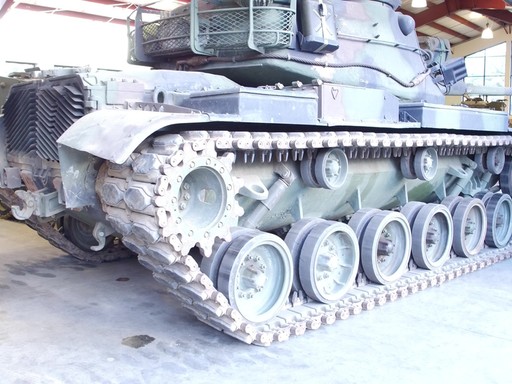
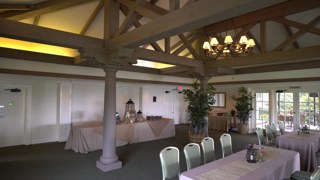
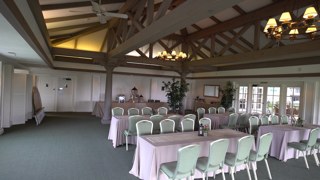
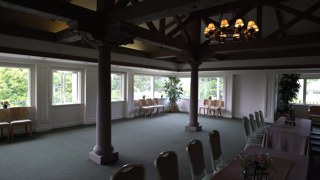
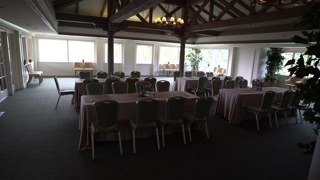
Tanks and Temples · Meetingroo · fourth trajectorycovisibility 0.91, 4.9 m, 44°
Context views (the first is the trajectory start)
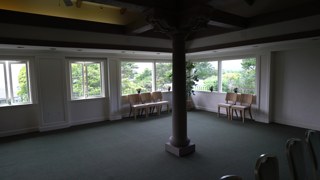
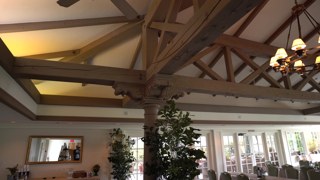
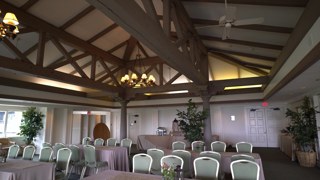
Ground-truth keyframes 0, 3, 6, 9, 12
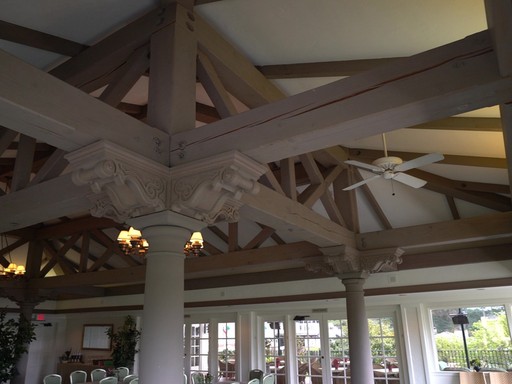
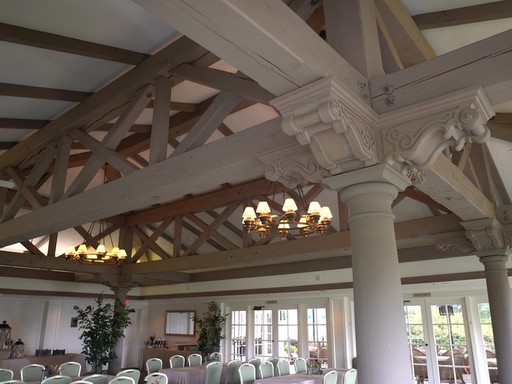
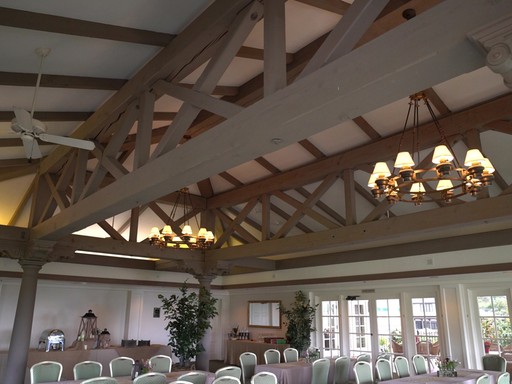
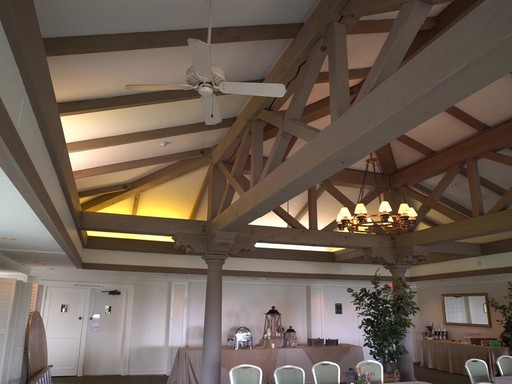
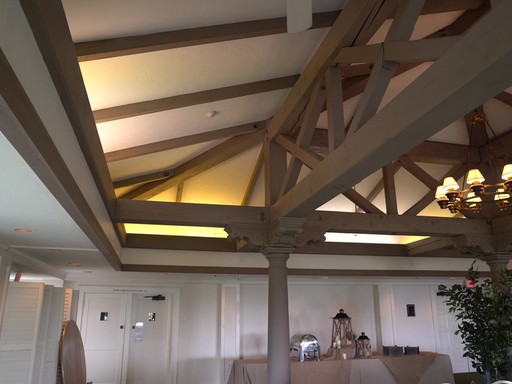
Tanks and Temples · Museumcovisibility 0.87, 3.8 m, 154°
Context views (the first is the trajectory start)
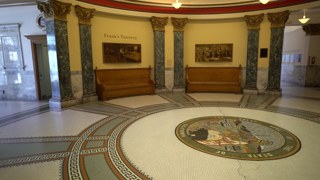
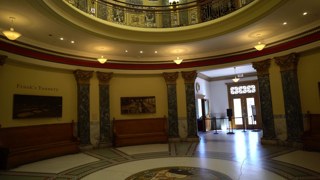
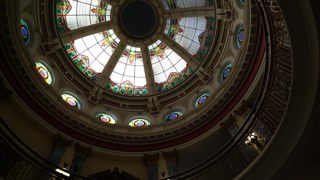
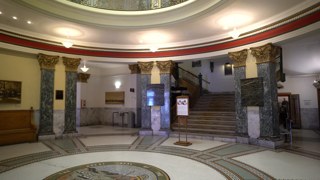
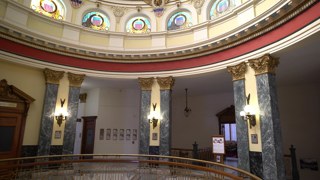
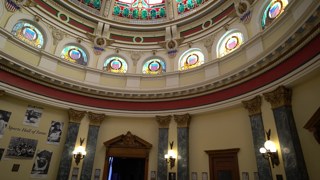
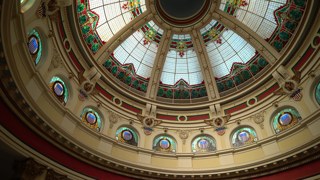
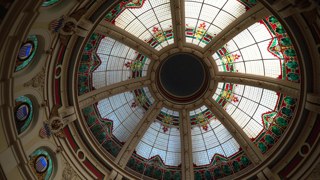
Ground-truth keyframes 0, 3, 6, 9, 12
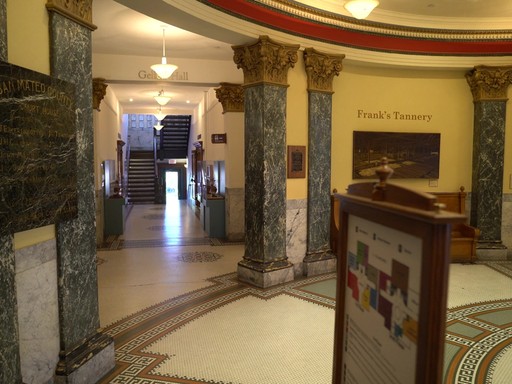
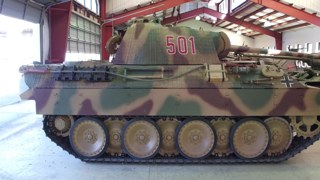
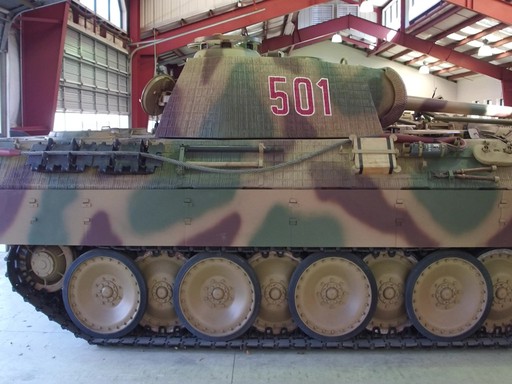
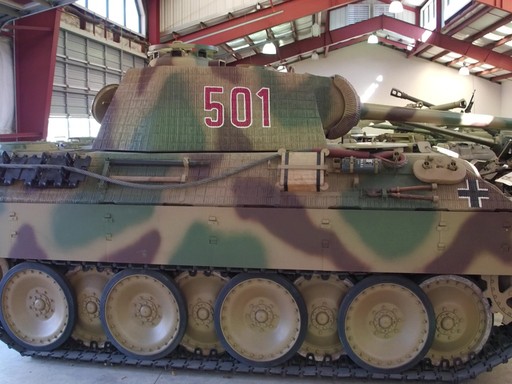
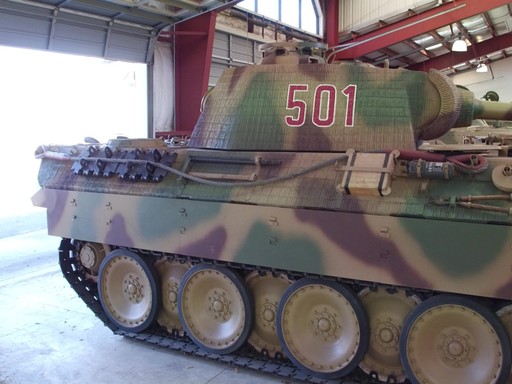
Tanks and Temples · Panthercovisibility 0.93, 4.0 m, 40°
Context views (the first is the trajectory start)
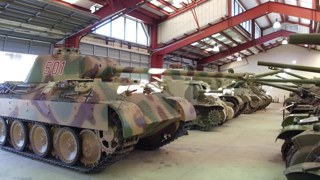
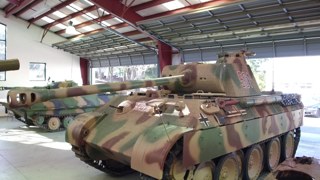
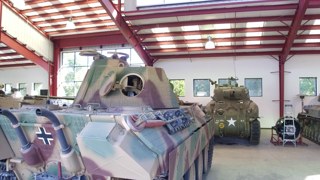
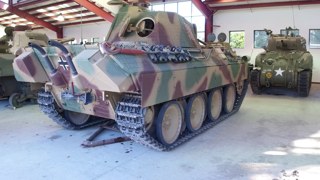
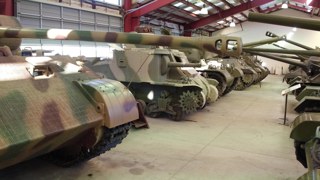
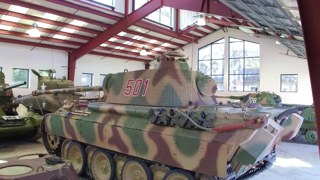
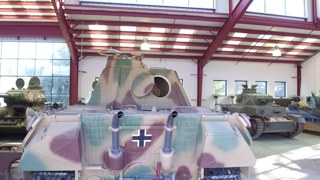
Ground-truth keyframes 0, 3, 6, 9, 12
References
- Zhou et al. Stable Virtual Camera: generative view synthesis with diffusion models. arXiv 2503.14489.
- Ren et al. GEN3C: 3D-informed world-consistent video generation with precise camera control. CVPR 2025.
- Wu et al. FrameCrafter: novel view synthesis as video completion. ECCV 2026.
- Lan et al. Holo4D: holistic 4D reconstruction as geometric control for video diffusion. arXiv 2610.25276.
- Yu et al. TrajectoryCrafter: redirecting camera trajectory for monocular videos via diffusion models. ICCV 2025.
- Jiang et al. AnySplat: feed-forward 3D Gaussian splatting from unconstrained views. ACM TOG (SIGGRAPH Asia) 2025.
- Zhang and Agrawala. Packing input frame context in next-frame prediction models for video generation (FramePack). arXiv 2504.12626.
- MiniMax. MiniMax-H3 (Ref2VA), open-weight video generation model.
- Code Video Model Team. Code Video Model. Technical report, 2026.
- Yeshwanth et al. ScanNet++: a high-fidelity dataset of 3D indoor scenes. ICCV 2023.
- Knapitsch et al. Tanks and Temples: benchmarking large-scale scene reconstruction. SIGGRAPH 2017.
- Heusel et al. GANs trained by a two time-scale update rule converge to a local Nash equilibrium (FID). NeurIPS 2017.
- Stein et al. Exposing flaws of generative model evaluation metrics and their unfair treatment of diffusion models (FD-DINOv2). NeurIPS 2023.
- Huang et al. VBench: comprehensive benchmark suite for video generative models. CVPR 2024.
- Ding et al. Image quality assessment: unifying structure and texture similarity (DISTS). TPAMI 2020.
- Wu et al. Q-Align: teaching LMMs for visual scoring via discrete text-defined levels. ICML 2024.
- Yu et al. Long-term photometric consistent novel view synthesis with diffusion models (TSED). ICCV 2023.